AI search and crawlers
Assistants fetch your pages to train, cite and answer. This series shows how to identify them, how robots.txt and llms.txt compare with real hits, and how many visitors they actually send back.
AI crawlers are now a visible share of traffic on most sites. These articles explain how TapCub separates them from search crawlers and people, how to read the crawler ledger, and how to write and verify an llms.txt file. The goal is a decision you can defend: allow, limit or block, based on what each bot takes and what it returns.
Articles in AI Search
39 articles
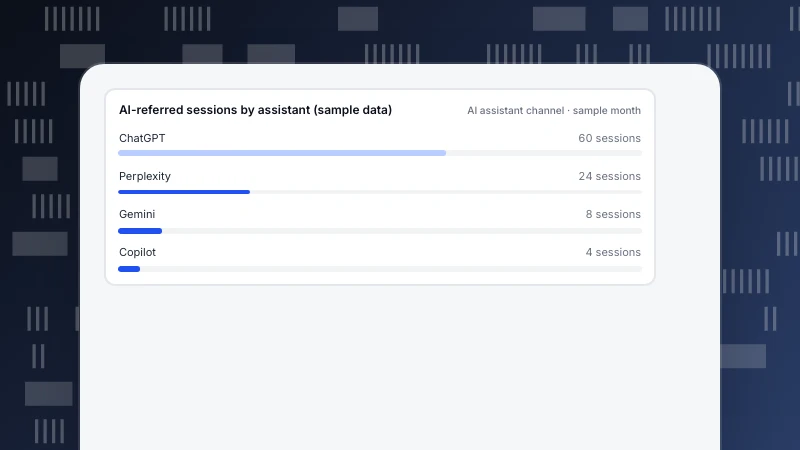
AI Referral Traffic: How to Spot and Measure It
AI referral traffic is people clicking links in ChatGPT, Perplexity or Gemini answers. How it differs from AI crawlers, how it shows up in analytics, why it is undercounted, and how to measure it.
Read more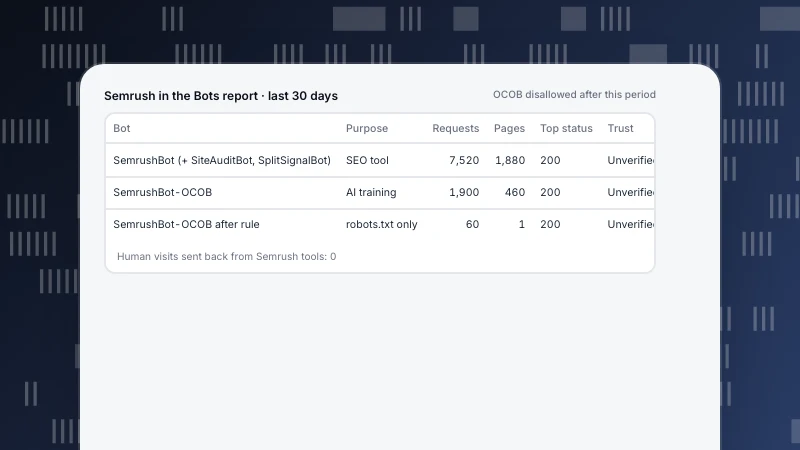
SemrushBot: The 10-Agent Family and How to Control Each One
SemrushBot is a family of ten Semrush crawlers with independent robots.txt tokens. What each does, how to keep SEO data while opting out of SemrushBot-OCOB, how to verify requests, and how to decide per goal.
Read more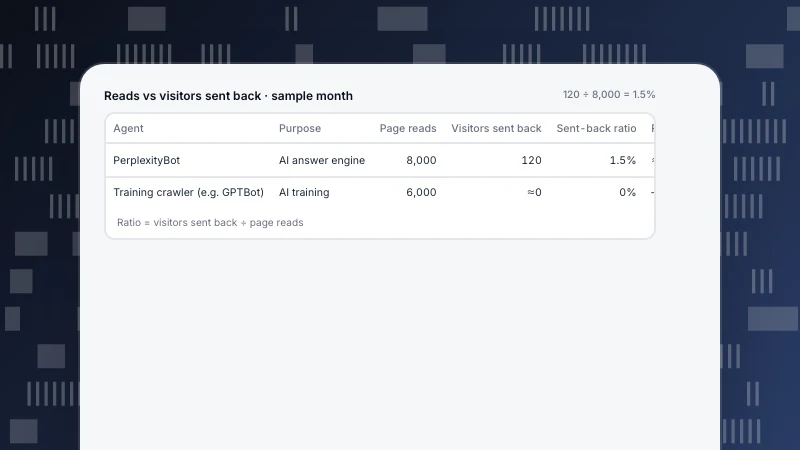
PerplexityBot: What It Reads, What It Sends Back, and Whether to Allow It
PerplexityBot reads pages so Perplexity answers can cite your site; Perplexity-User fetches on user request. What each does, robots.txt rules, IP verification, and a reads-vs-visitors rule for allowing or blocking.
Read more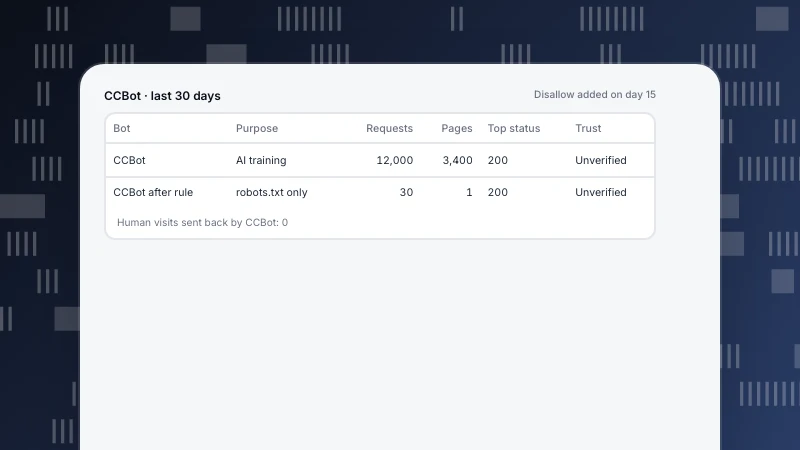
CCBot: Common Crawl's Dataset Crawler and What Blocking It Changes
CCBot builds Common Crawl's free public dataset — a documented training source for GPT-3, LLaMA and BLOOM. What it fetches, how to verify it, robots.txt rules, and why blocking only shapes future snapshots.
Read more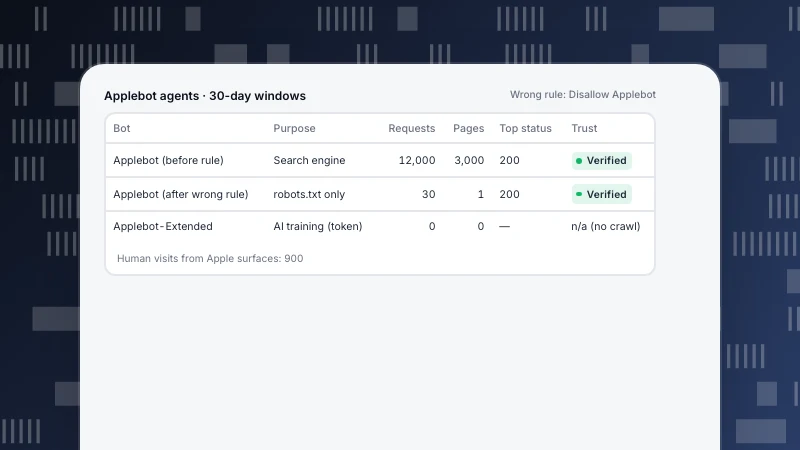
Applebot and Applebot-Extended: Two Agents and How to Control Each One
Applebot crawls for Spotlight, Siri and Safari search; Applebot-Extended is only a robots.txt switch for AI training. What each does, three rule choices, DNS and IP verification, and a worked example of what the wrong block costs.
Read more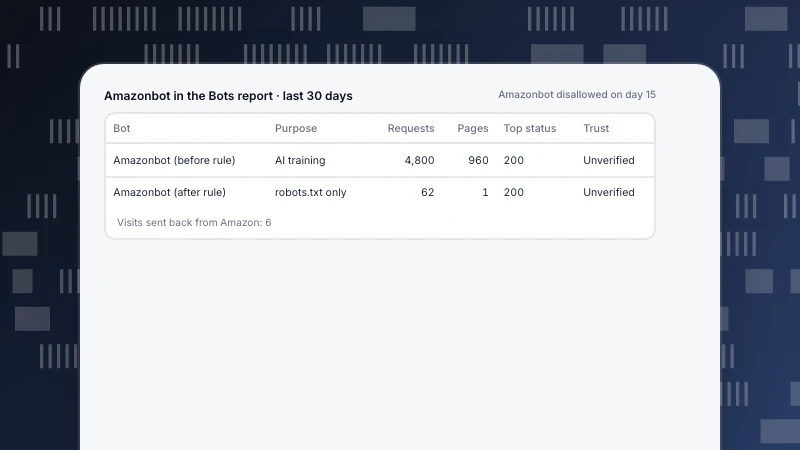
Amazonbot: Amazon's Three Crawlers and How to Control Each One
Amazonbot is Amazon's crawler whose reads may be used to train Amazon AI models — one of three Amazon agents with independent robots.txt settings. What each does, rules per goal, IP verification, and a worked example of reads versus traffic sent back.
Read more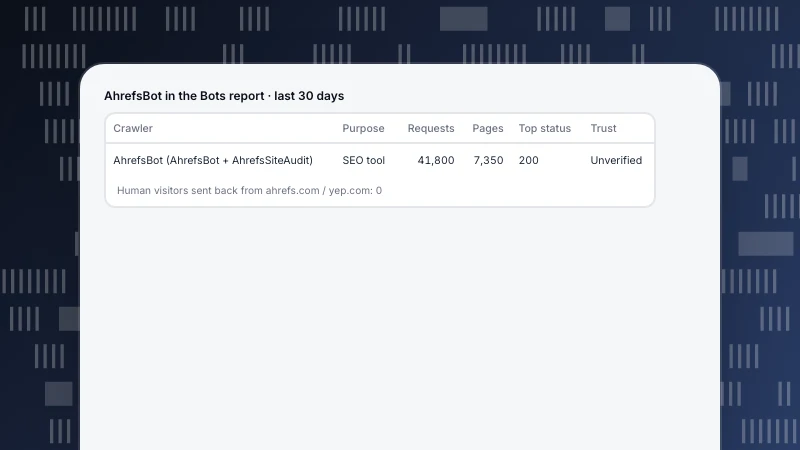
AhrefsBot: What It Does and Whether to Allow or Block It
AhrefsBot reads your site for Ahrefs users — including competitors — and sends back no visitors. What its two crawlers do, robots.txt allow/block/rate-limit rules, verification, and how to decide.
Read more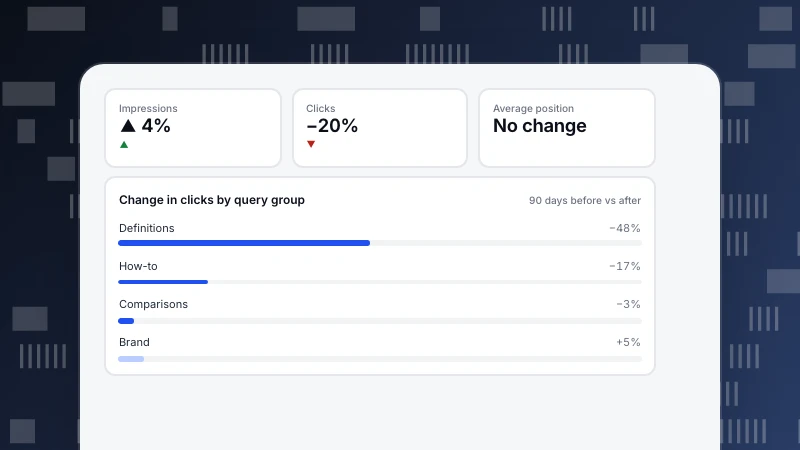
Zero-click searches: what the data shows and how to adapt
About 60% of Google searches now end without a click. What zero-click searches are, which queries are most affected, a worked before/after where impressions rose 4% and clicks fell 20%, and seven ways to adapt.
Read more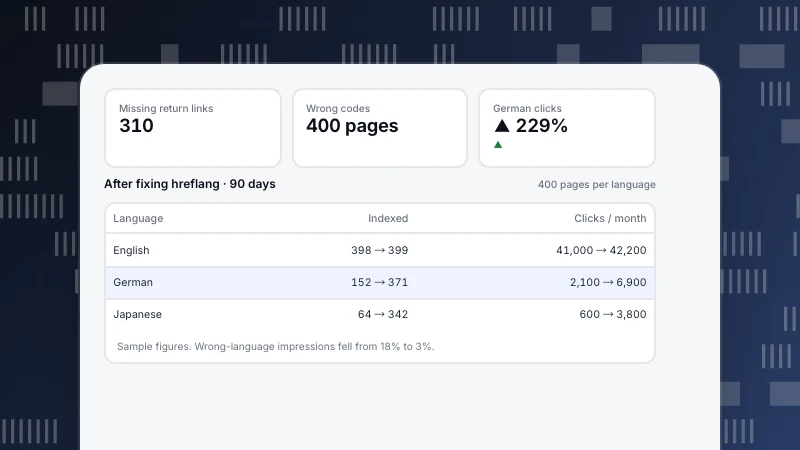
Multilingual SEO: URL structure, hreflang and a worked audit
How to rank a website in several languages: choosing a URL structure, hreflang rules that cause most errors, localizing keywords, and a worked audit where fixing hreflang tripled German clicks and lifted Japanese clicks sixfold.
Read more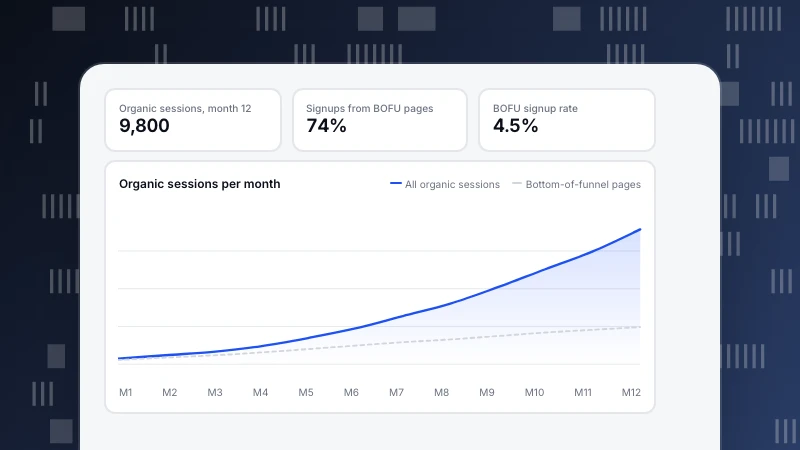
SEO for startups: a 12-month plan that turns searches into signups
When a startup should start SEO, which keywords a new domain can actually win, a 12-month plan, and a worked year where bottom-of-funnel pages brought 28% of organic traffic and 74% of signups.
Read more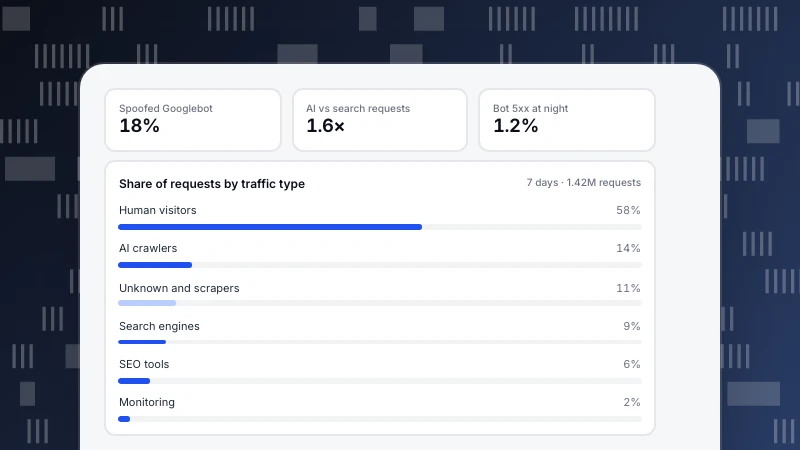
Web crawler: how it works, types of crawlers and how to verify them
What a web crawler is, the six steps every crawler follows, search vs AI training vs AI search crawlers, a worked week of server logs with spoofed Googlebots, and how to verify and control crawlers.
Read more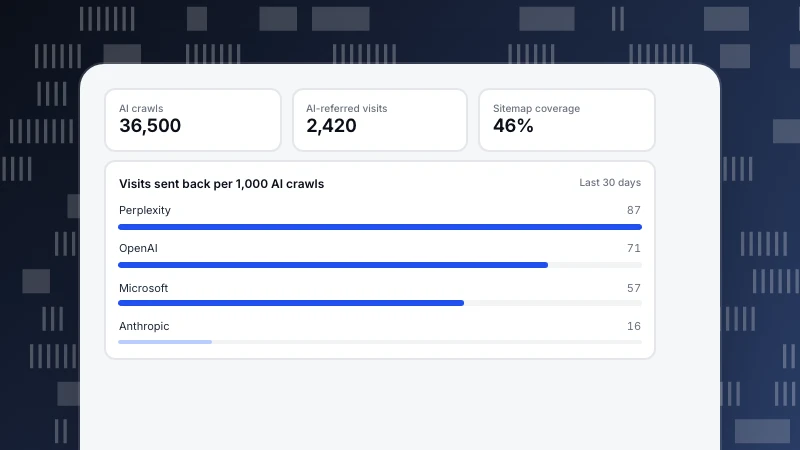
AI visibility: how to measure and improve it in AI search
AI visibility is how often AI answers read, cite and send people to your site. Three layers to measure, four metrics, a worked month of AI traffic by operator, and seven ways to improve it.
Read more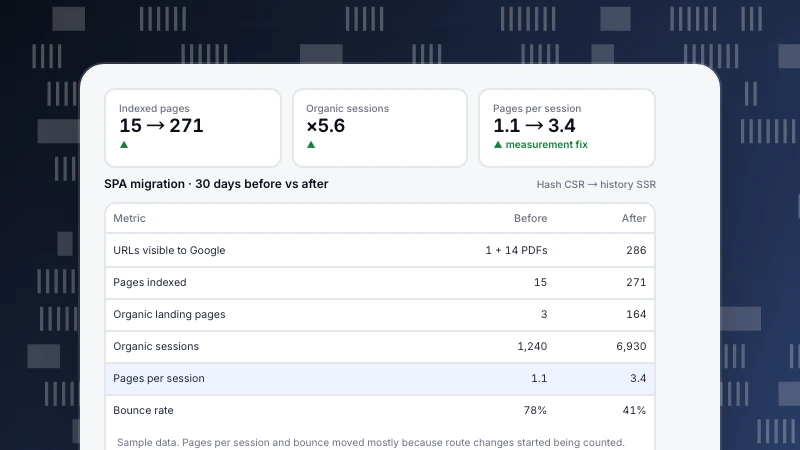
Single-page application SEO: routing, status codes and analytics
Single-page apps need every client-side view to behave like a real page for crawlers and analytics. Seven requirements, history vs hash routing, soft 404 fixes, a migration that grew indexed pages from 15 to 271, and how to count SPA pageviews correctly.
Read more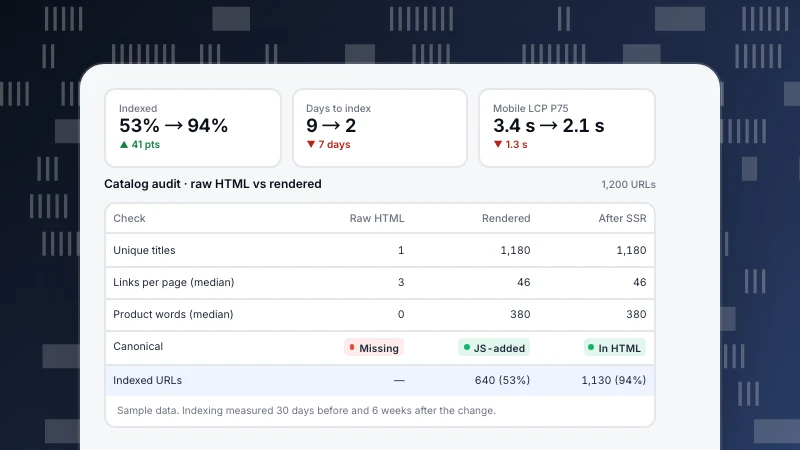
JavaScript SEO: how Google and AI crawlers handle JS, and how to fix it
JavaScript SEO makes sure crawlers can see content that scripts produce. How Google crawls, renders and indexes JS, why most AI crawlers see an empty shell, rendering strategies, common problems and a catalog audit that went from 53% to 94% indexed.
Read more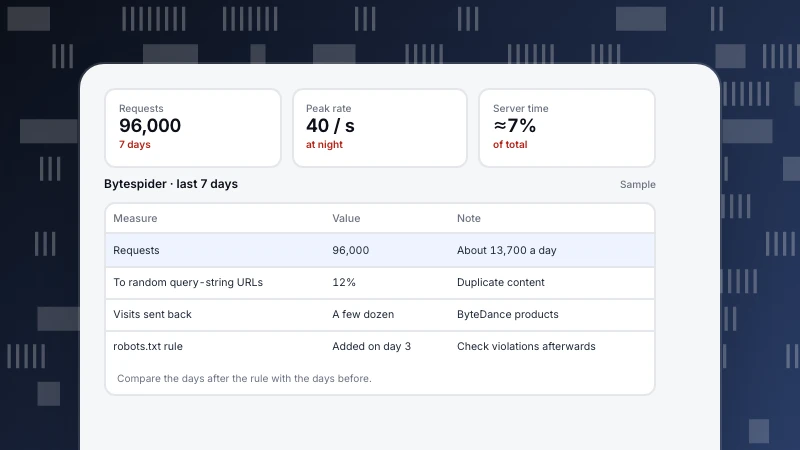
Bytespider: What It Is and How to Control It
Bytespider is the web crawler operated by ByteDance, the company behind TikTok. Site owners often notice it because of its request volume. Its user agent, a worked week measuring its load and robots.txt compliance, and the options from robots.txt to a firewall block.
Read more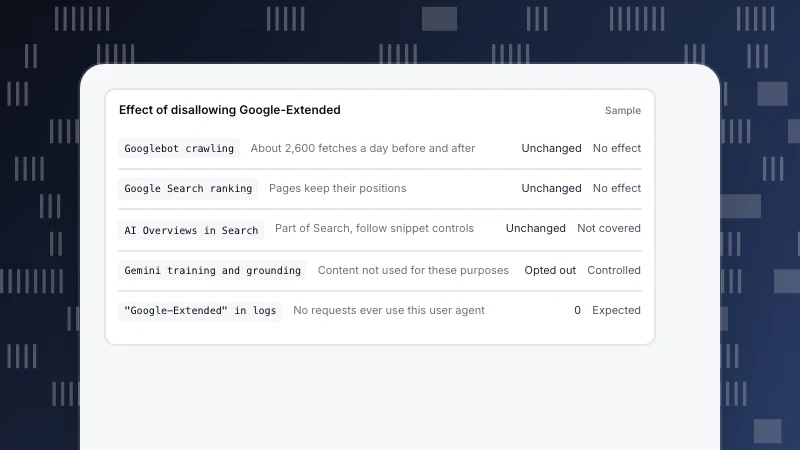
Google-Extended: What It Controls and How to Use It in robots.txt
Google-Extended is a robots.txt token, not a separate crawler. It lets you choose whether content Google crawls may be used for Gemini models and some other AI products, without affecting Google Search. What it controls, what it does not, and how to set it.
Read more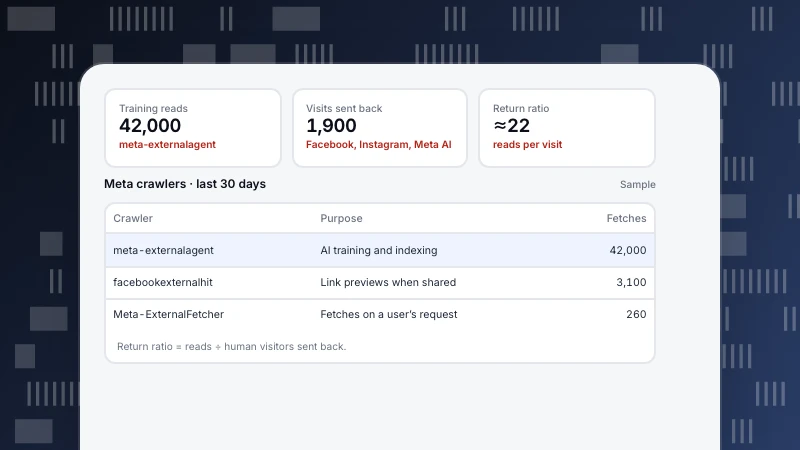
Meta-ExternalAgent: What Meta’s AI Crawler Does and How to Control It
Meta-ExternalAgent is the crawler Meta uses to collect web content for AI training and indexing. How it differs from Meta’s link preview crawler, how to verify it, a worked month comparing what it reads with the visitors Meta sends back, and robots.txt rules.
Read more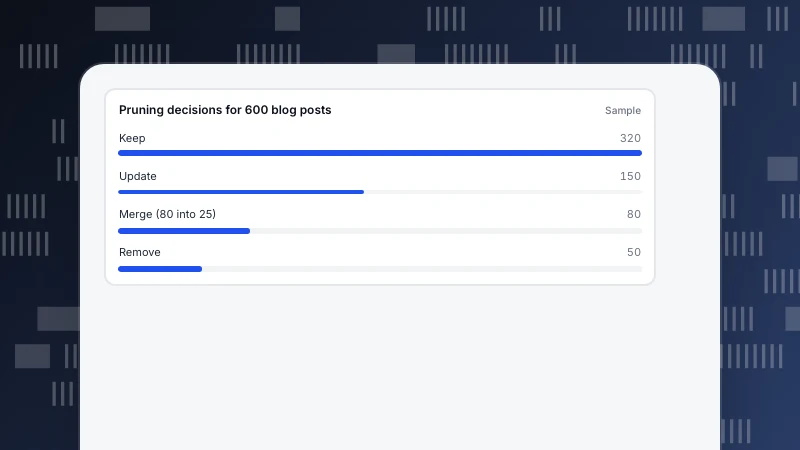
Content Pruning: When to Update, Merge or Remove Old Pages
Content pruning means reviewing old pages and improving, merging or removing the ones that no longer earn their place. Decision rules using traffic, links and conversions, a worked pruning of 600 posts, and how to remove pages without losing value.
Read more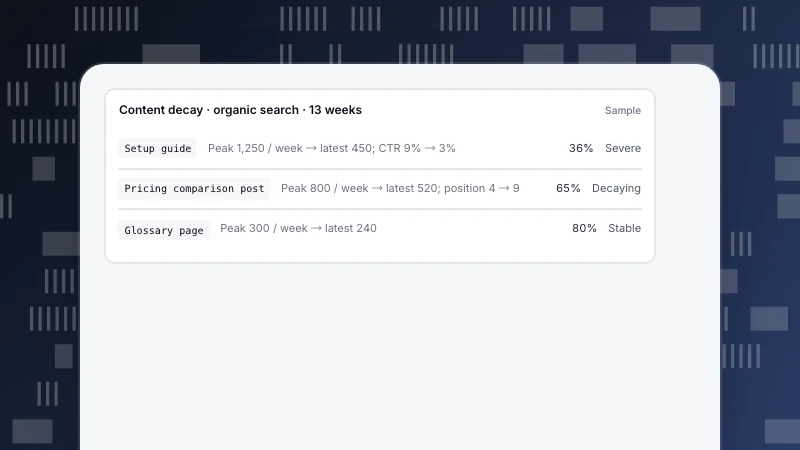
Content Decay: How to Spot It, Diagnose It and Fix It
Content decay is the gradual loss of traffic on pages that used to perform. How to define it with numbers, rule out seasonality and site-wide drops, diagnose by impressions, position and CTR, and choose between refresh, merge and leave alone.
Read more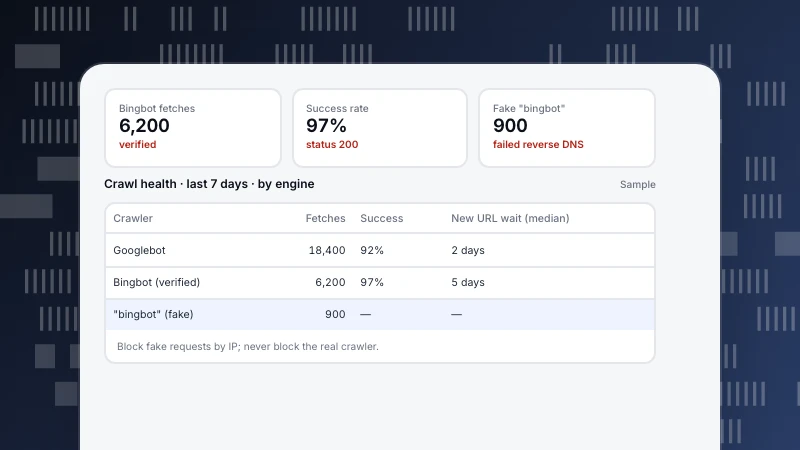
Bingbot: What It Is, How to Verify It and Control Its Crawling
Bingbot is Microsoft’s web crawler for Bing search. Its user agents, how to verify real Bingbot by reverse DNS, a worked week comparing it with Googlebot (with fake Bingbot traffic), how to control its crawl rate and how IndexNow speeds up discovery.
Read more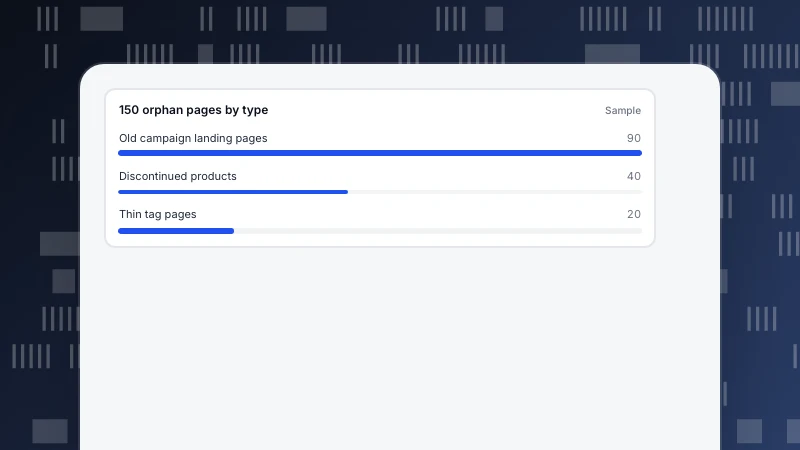
Orphan Pages: How to Find and Fix Them
Orphan pages exist on your site but no other page links to them, so visitors and search engines struggle to find them. How to find them by comparing URL lists, a worked example of 150 orphans, and when to link, redirect or remove.
Read more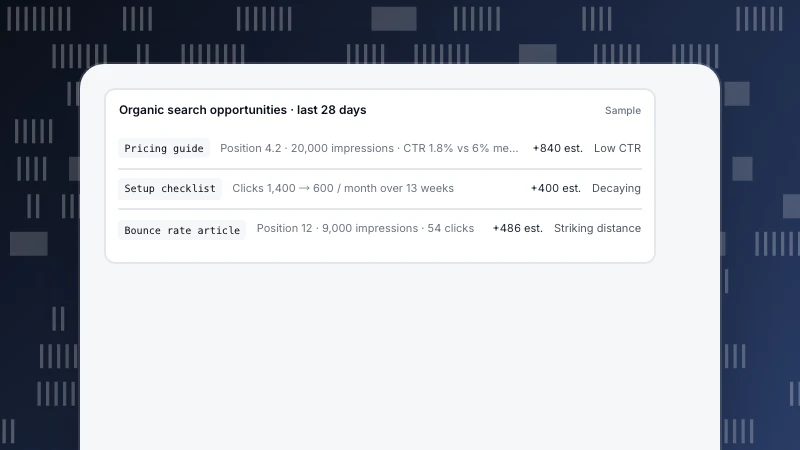
How to Improve Organic Search: Start With What You Already Rank For
The fastest organic search gains usually come from pages that already rank: fix titles with low CTR, push pages from positions 8–20 into the top 5, refresh decaying content, and remove technical blockers. A worked example with click estimates.
Read more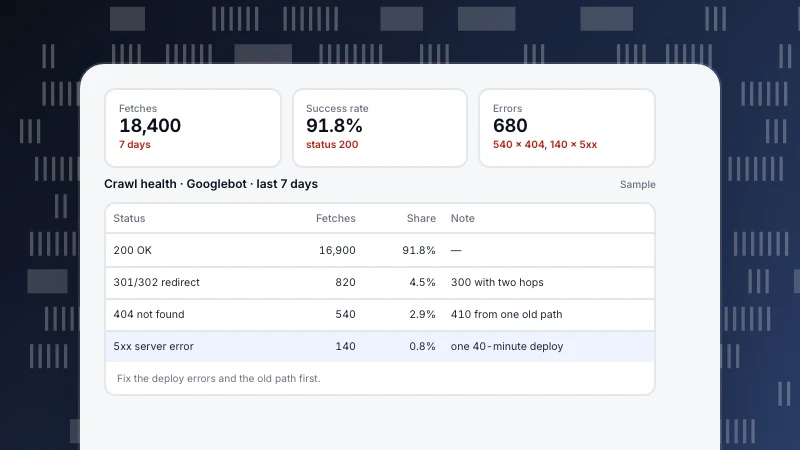
Crawl Errors: Types, Causes and How to Fix Them
Crawl errors are failed requests from search engine bots: DNS and server errors, timeouts, 404s and redirect problems. The main types, what causes them, a worked week of Googlebot data, and the order to fix them in.
Read more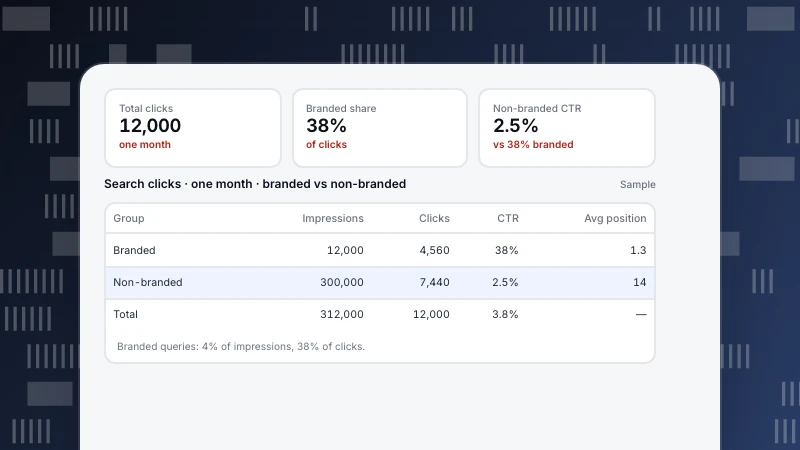
Branded vs Non-Branded Keywords: What to Track and Report
Branded keywords include your brand name; non-branded keywords describe the problem. They behave very differently in search. How to split them in your own data, a worked example, and which one shows real SEO growth.
Read more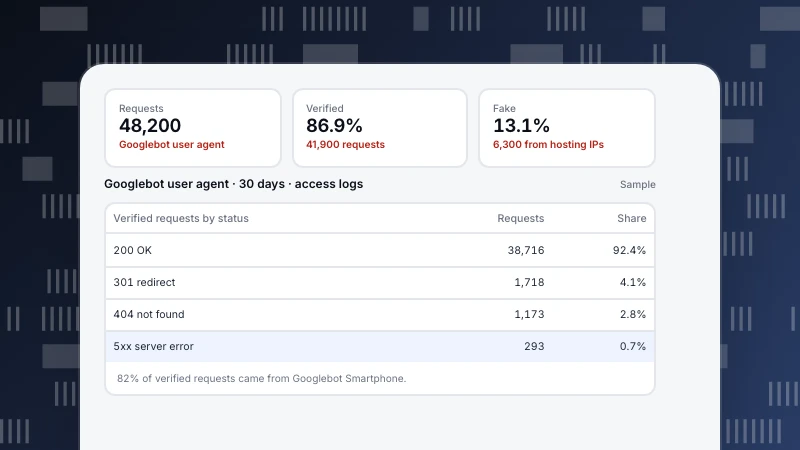
Googlebot: What It Is, How It Crawls and How to Verify It
Googlebot is the crawler Google uses to fetch pages for Search. How it crawls and renders, the other Google crawlers you will see in logs, how to tell a real Googlebot from a fake one, and a sample month of log data.
Read more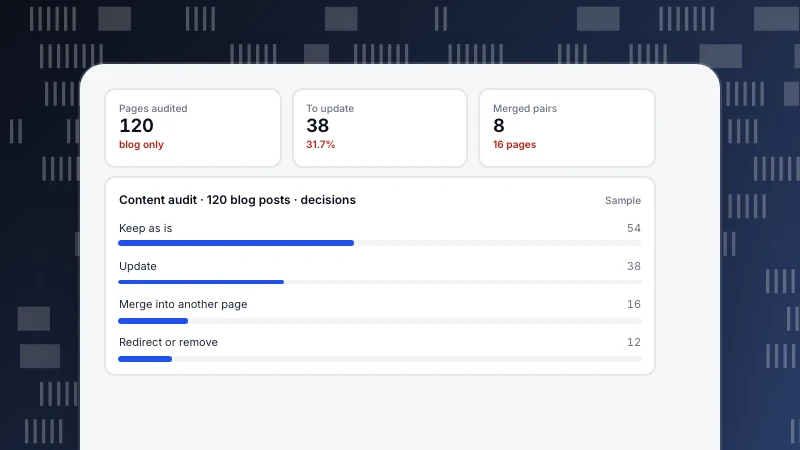
Content Audit: How to Review Every Page and Decide What to Do
A content audit lists every page with its traffic, conversions, links and trend, then decides to keep, update, merge or remove it. The data to collect, decision rules, and a worked sample of 120 pages.
Read more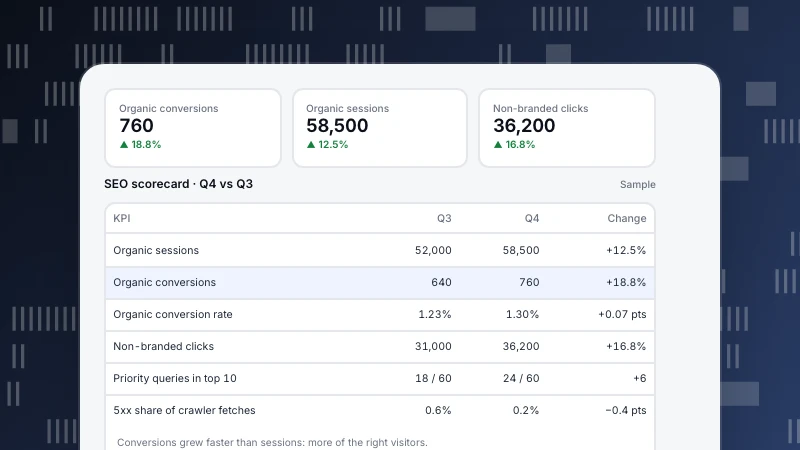
SEO KPIs: 10 Metrics That Show Whether SEO Is Working
Not every SEO metric is a KPI. Ten SEO KPIs in three tiers, business, visibility and technical health, with formulas, data sources, a sample quarterly scorecard and how to set targets.
Read more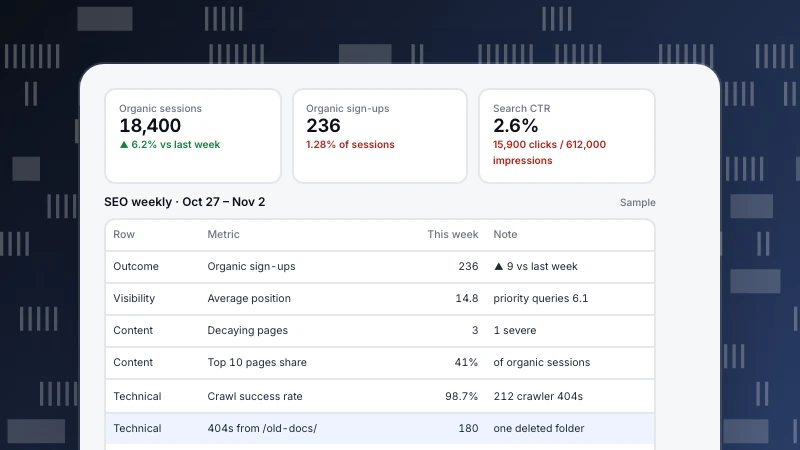
SEO Dashboard: What to Include and How to Read It
An SEO dashboard should answer three questions: is organic search bringing business, are we more visible, and is anything broken. A four-row layout, a sample weekly dashboard with numbers, and what to leave out.
Read more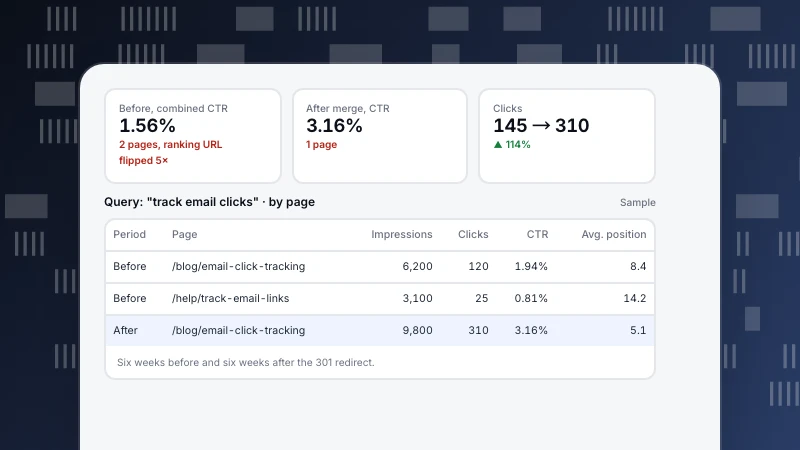
Keyword Cannibalization: How to Find It, Prove It and Fix It
Keyword cannibalization is when two of your pages compete for the same query and both rank worse than one would. How to tell real cannibalization from harmless overlap, a worked example with split clicks, and which fix to use.
Read more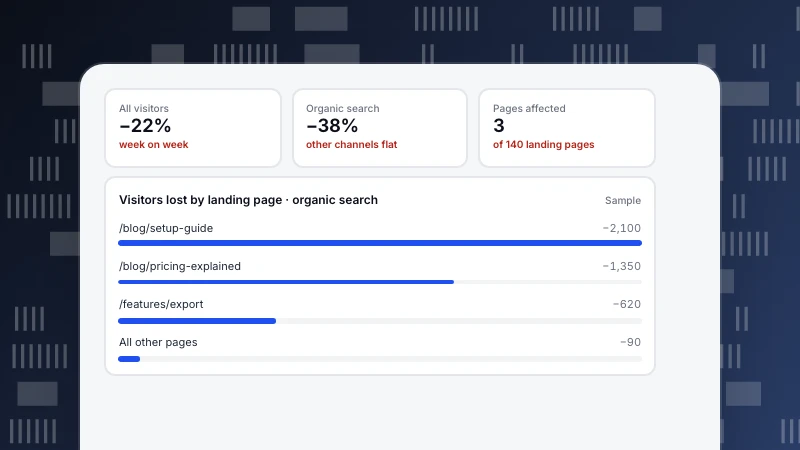
Sudden Drop in Website Traffic? A 15-Minute Triage
When website traffic drops suddenly, first check whether the drop is real, then find which channel, pages and devices it sits in. A step-by-step triage, a table of causes with their evidence, and a worked example.
Read more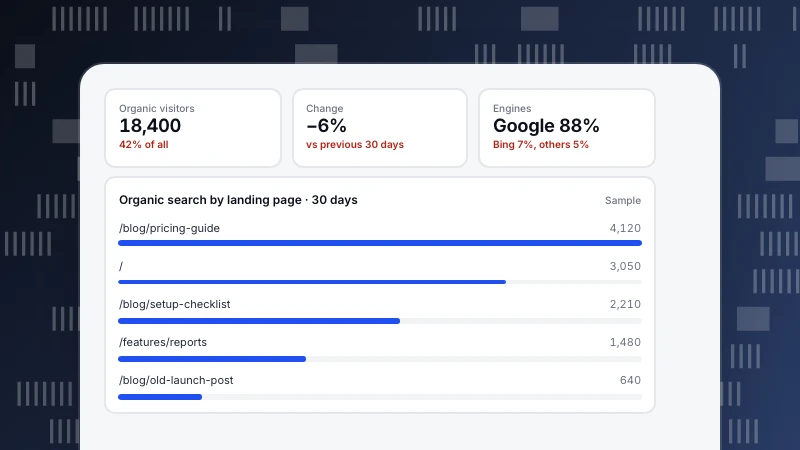
What Is Organic Traffic? How It Is Counted and How to Grow It
Organic traffic is visits from unpaid search results. How analytics decides a visit is organic, how it differs from paid and direct traffic, a sample breakdown, and a routine for growing it or explaining a drop.
Read more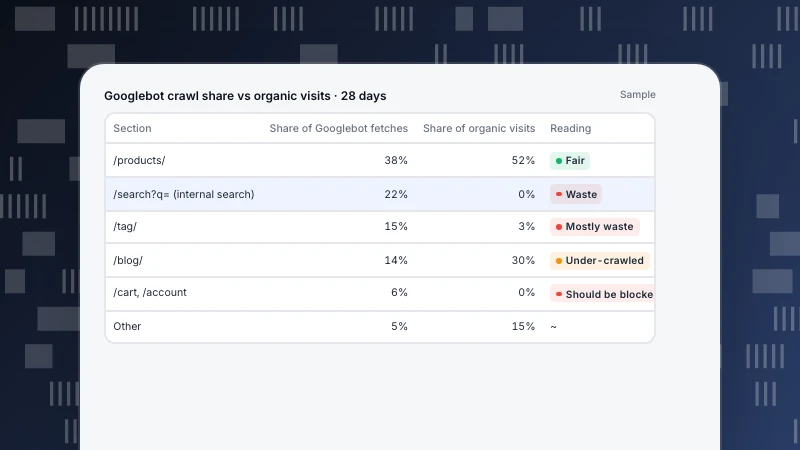
Log File Analysis for SEO: A Tool-Neutral Method in Six Questions
Server logs show what search engine crawlers actually request, not what a crawl tool assumes. How to get the logs, verify that Googlebot is real, and answer six questions that turn raw lines into SEO fixes.
Read more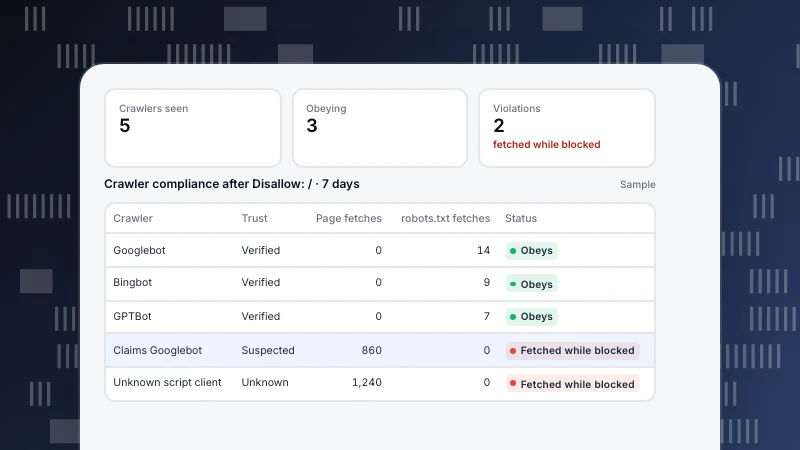
robots.txt Disallow All: What It Blocks, What It Doesn't, and Safer Variants
Two lines in robots.txt ask every crawler to stay off your whole site. What they actually do, what they do not (they do not hide URLs or protect anything), common variants and how Google resolves conflicts, and how to check which crawlers obey.
Read more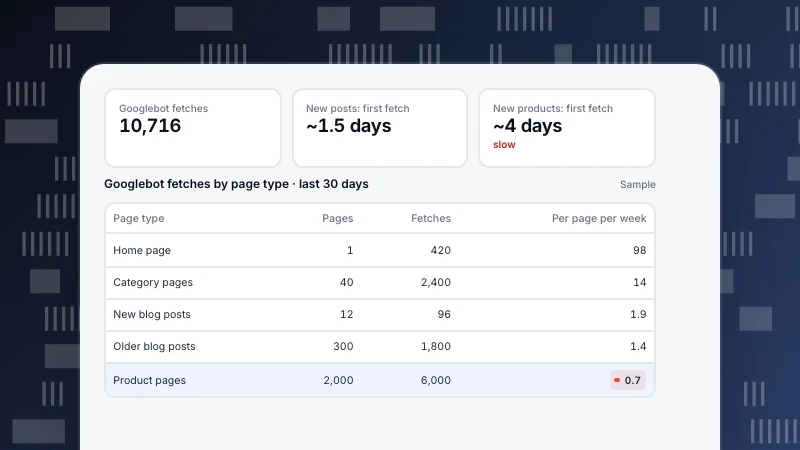
How Often Does Google Crawl a Site? Measure Yours, Then Speed It Up
Google has no fixed crawl schedule: your home page may be fetched many times a day and a deep product page once a month. How to measure crawl frequency on your own site by page type, and what actually gets new pages crawled sooner.
Read more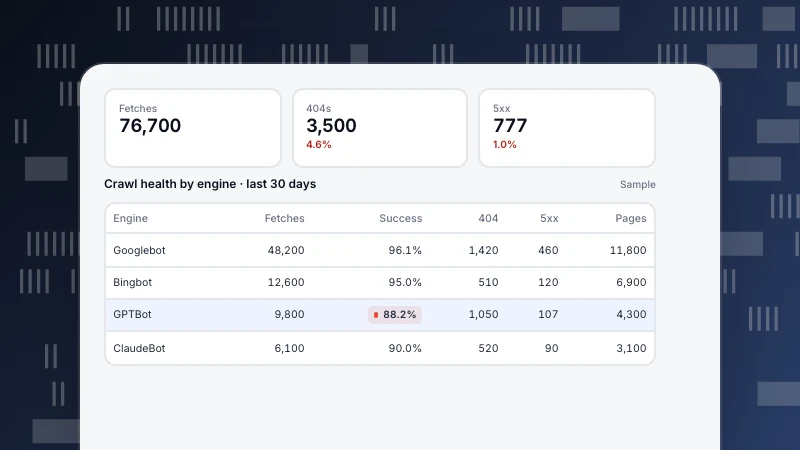
Crawl Budget: Does It Matter for Your Site, and Where Is It Going?
Crawl budget is how much a search engine is willing and able to crawl on your site. When it matters, what wastes it, and how to read server logs to see where search and AI crawlers actually spend their requests.
Read more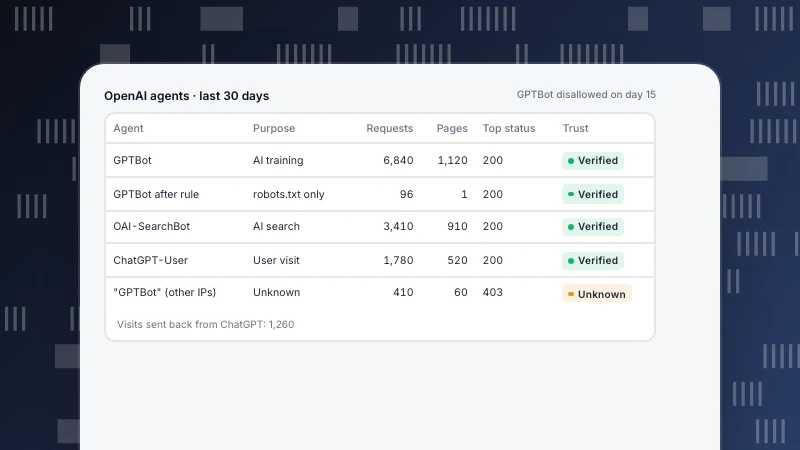
GPTBot: OpenAI's Four Crawlers and How to Control Each One
GPTBot is OpenAI's training crawler, one of four OpenAI agents with independent robots.txt settings. What each does, what opting out changes, rules for common goals, and how to verify and check them in your own data.
Read more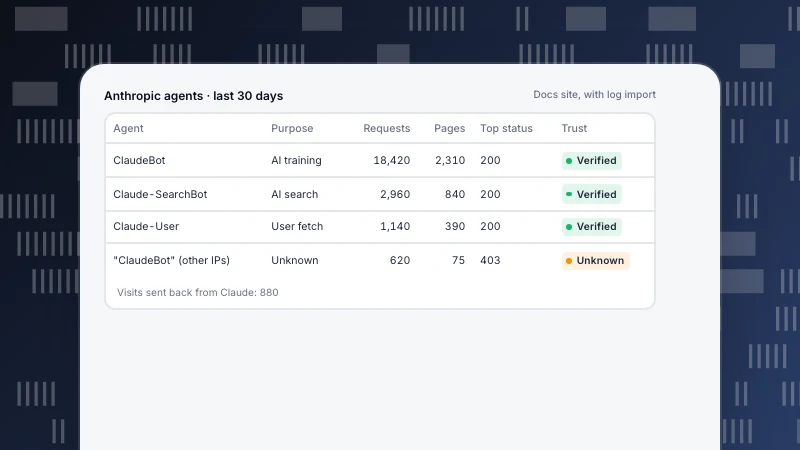
ClaudeBot: What It Crawls, How to Block It and How to Verify It
ClaudeBot is one of three Anthropic web agents. What each one does, what blocking it changes, robots.txt rules for common goals, how to verify requests against Anthropic's published IP list, and how to see ClaudeBot in your own data.
Read more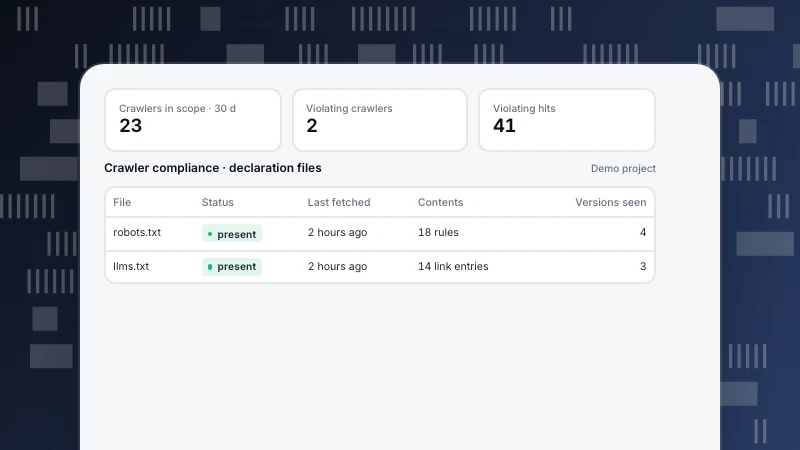
llms.txt: what to write, an example, and how to check whether anyone reads it
What llms.txt is and is not, the structure the proposal defines, a real example, how it should agree with robots.txt, and how to check in your server logs whether AI agents fetch it.
Read more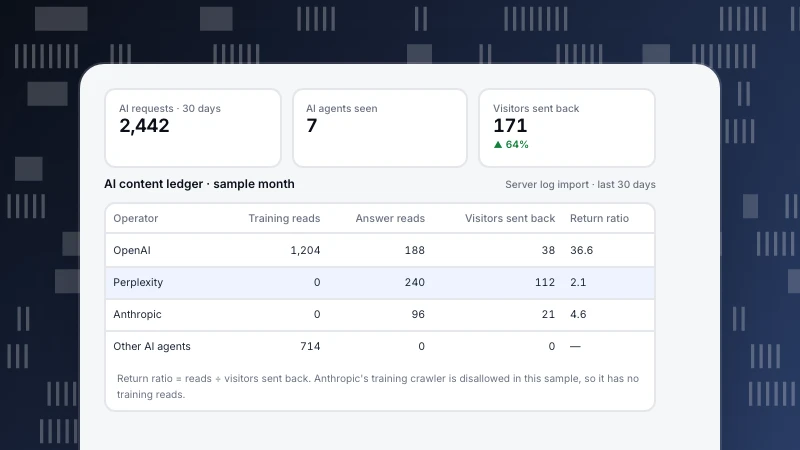
How to block AI crawlers: user agents, robots.txt rules and how to check them
GPTBot, ClaudeBot, Google-Extended and the rest do different jobs. Which AI crawlers to block, the robots.txt rules to use, what to enforce at the server, and how to check it worked.
Read moreOther categories
Each category answers a recurring question we hear from customers. Start with the one closest to your job.
Analytics
Definitions, funnels, retention and the data-quality questions behind every number.
304 articlesGrowth & Marketing
Acquisition, marketing, site and app operations, and how to pick the one stage worth fixing first.
238 articlesLive Chat
Proactive invites, translation and turning support conversations into conversions.
78 articlesProduct News
What shipped, why we built it that way, and how to turn it on.
64 articles