AI search
10 articles tagged “AI search”. Tags cut across categories, so you may find analytics, chat and product notes side by side.
Tagged AI search
10 articles
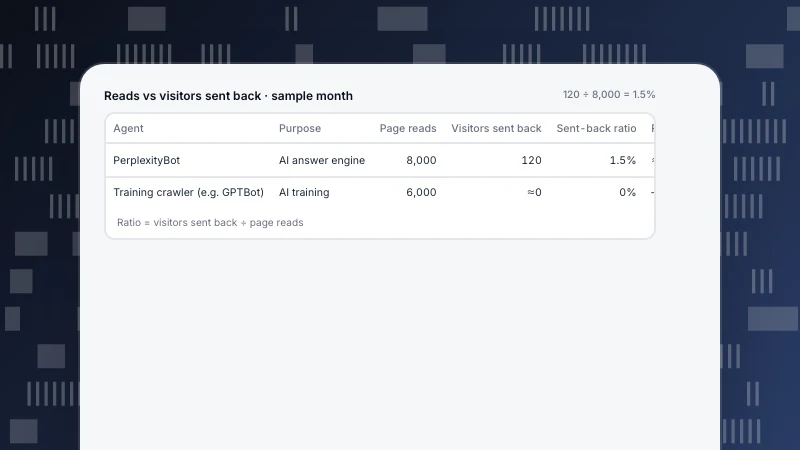
PerplexityBot: What It Reads, What It Sends Back, and Whether to Allow It
PerplexityBot reads pages so Perplexity answers can cite your site; Perplexity-User fetches on user request. What each does, robots.txt rules, IP verification, and a reads-vs-visitors rule for allowing or blocking.
Read more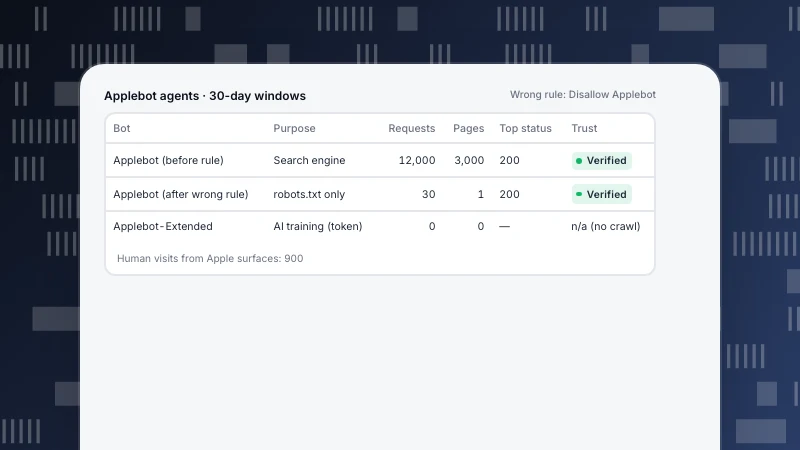
Applebot and Applebot-Extended: Two Agents and How to Control Each One
Applebot crawls for Spotlight, Siri and Safari search; Applebot-Extended is only a robots.txt switch for AI training. What each does, three rule choices, DNS and IP verification, and a worked example of what the wrong block costs.
Read more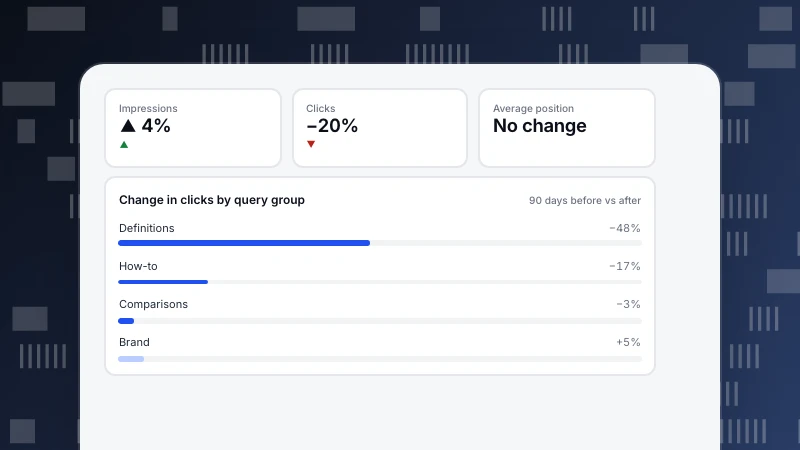
Zero-click searches: what the data shows and how to adapt
About 60% of Google searches now end without a click. What zero-click searches are, which queries are most affected, a worked before/after where impressions rose 4% and clicks fell 20%, and seven ways to adapt.
Read more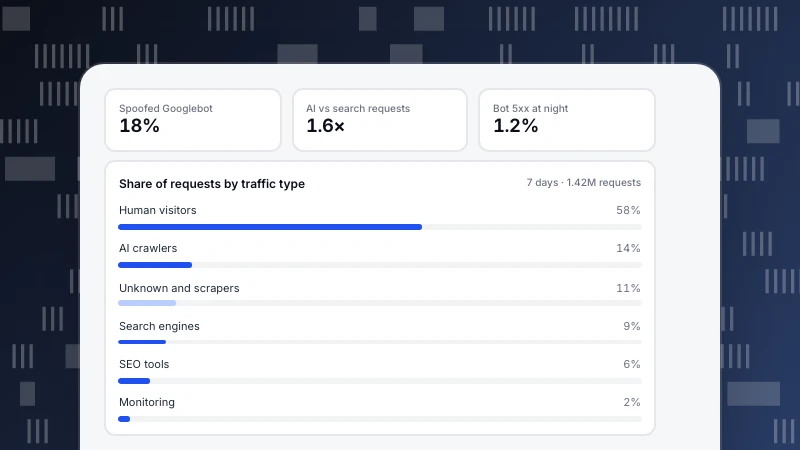
Web crawler: how it works, types of crawlers and how to verify them
What a web crawler is, the six steps every crawler follows, search vs AI training vs AI search crawlers, a worked week of server logs with spoofed Googlebots, and how to verify and control crawlers.
Read more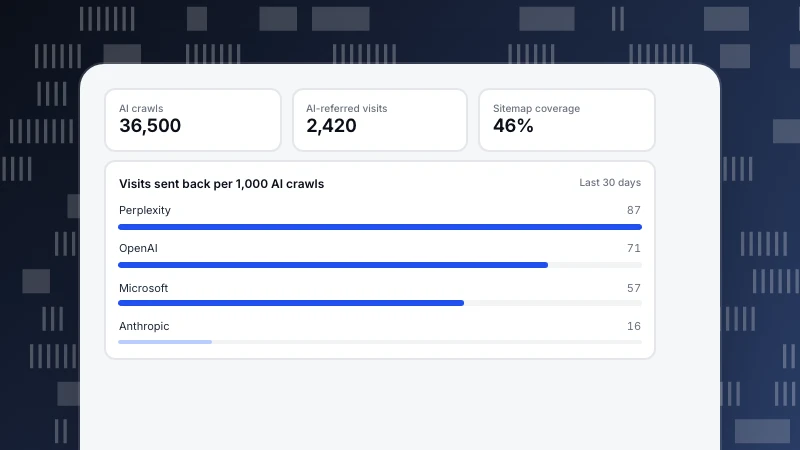
AI visibility: how to measure and improve it in AI search
AI visibility is how often AI answers read, cite and send people to your site. Three layers to measure, four metrics, a worked month of AI traffic by operator, and seven ways to improve it.
Read more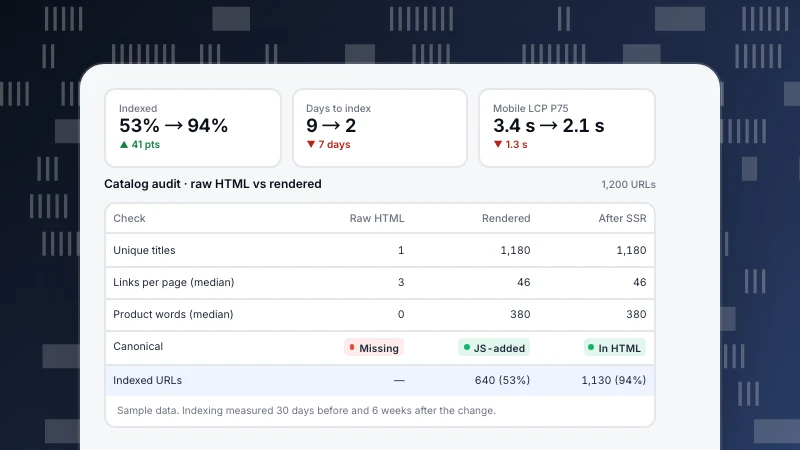
JavaScript SEO: how Google and AI crawlers handle JS, and how to fix it
JavaScript SEO makes sure crawlers can see content that scripts produce. How Google crawls, renders and indexes JS, why most AI crawlers see an empty shell, rendering strategies, common problems and a catalog audit that went from 53% to 94% indexed.
Read more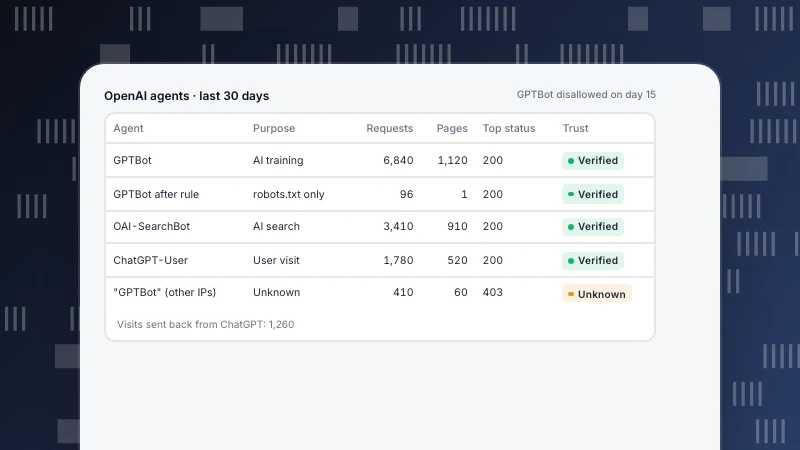
GPTBot: OpenAI's Four Crawlers and How to Control Each One
GPTBot is OpenAI's training crawler, one of four OpenAI agents with independent robots.txt settings. What each does, what opting out changes, rules for common goals, and how to verify and check them in your own data.
Read more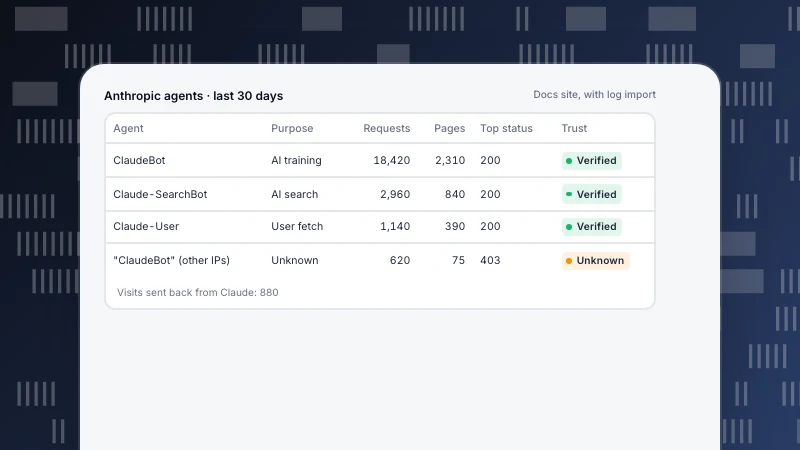
ClaudeBot: What It Crawls, How to Block It and How to Verify It
ClaudeBot is one of three Anthropic web agents. What each one does, what blocking it changes, robots.txt rules for common goals, how to verify requests against Anthropic's published IP list, and how to see ClaudeBot in your own data.
Read more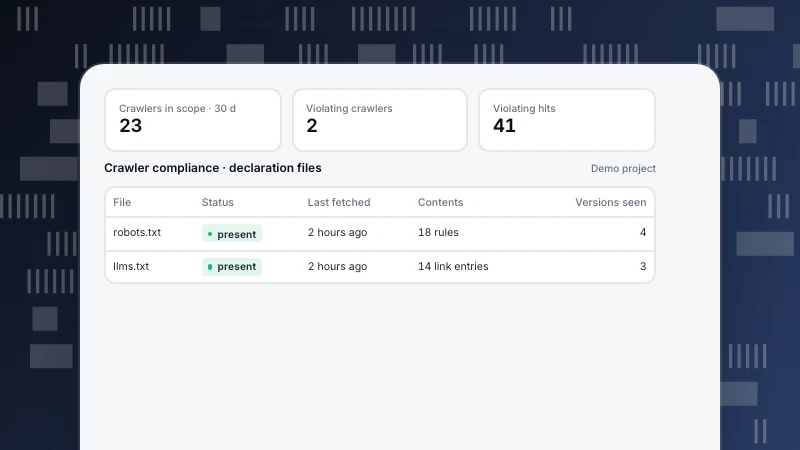
llms.txt: what to write, an example, and how to check whether anyone reads it
What llms.txt is and is not, the structure the proposal defines, a real example, how it should agree with robots.txt, and how to check in your server logs whether AI agents fetch it.
Read more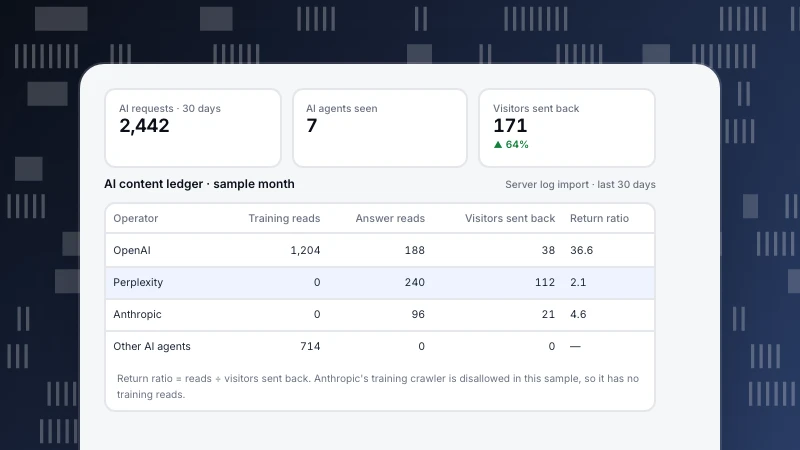
How to block AI crawlers: user agents, robots.txt rules and how to check them
GPTBot, ClaudeBot, Google-Extended and the rest do different jobs. Which AI crawlers to block, the robots.txt rules to use, what to enforce at the server, and how to check it worked.
Read more