Try it on your own data
Every report in this article is in the free plan. One snippet for web and apps, up to 10 sites.
Start freellms.txt is a short Markdown guide to your site for language models. It is young, voluntary and easy to overrate. This guide covers what the proposal actually defines, what to write, a trimmed real example, how the file should agree with robots.txt, and how to check from your server logs whether any agent reads it.
What you will learn
- llms.txt is curation, not permission; Google says its AI features do not need it
- The structure: an H1, a summary blockquote, then H2 sections of described links
- Verify in server logs: fetches of /llms.txt, and how many fetched pages you listed
What changed · Nov 3, 2026
Rewritten with the format from the proposal, Google's position, a real example and server-log verification. Removed an unsupported metric.
What llms.txt is, and is notWhat to put in itHow it relates to robots.txtCheck whether anyone reads itKeep it currentCommon mistakesFAQ
What llms.txt is, and is not
Section updated
llms.txt is a Markdown file at the root of a site that gives large language models a short, curated guide to its content: who you are, in one paragraph, and the pages worth reading, each with a one-line description. Jeremy Howard proposed it in September 2024 (llmstxt.org). It is a community proposal, not a standard, and nothing enforces it.
Think of three files. A sitemap lists everything, for search engines, with no opinion. robots.txt sets permissions: which agents may fetch which paths. llms.txt is curation, written for a reader that will summarise you to someone else. It grants and denies nothing. A crawler you block in robots.txt will not read it, and a crawler you allow is free to ignore it.
Be realistic about what it does for search. Google says you do not need to create new machine-readable files, AI text files or markup to appear in its AI features (Google Search Central). So treat llms.txt as low-cost insurance for assistants and agents that do read it: an hour to write, a few minutes a quarter to maintain, and an effect you check in your own logs rather than take on faith.
What to put in it
Section updated
The proposal defines a simple structure, and only the first element is required: an H1 with the site or project name. After that, in order: a blockquote with a short summary, optional paragraphs of detail, and H2 sections containing lists of links, each written as a Markdown link followed by a colon and a description. A section named “Optional” marks links a reader can skip when it is short on context.
In practice:
- Summary first. One paragraph a model could quote as-is: what you make, for whom, and the facts people get wrong (pricing currency, what you do not do).
- Group links by purpose. Product pages, documentation, pricing and policies, and a few articles that answer common questions well.
- Describe, do not sell. Assistants quote descriptions, and “the leading platform” reads badly in someone else’s answer. Say what the reader will find.
- Use absolute URLs to the canonical page, not to a redirect or a tracking link.
- Curate. A dozen to a few dozen links. Listing every page turns it back into a sitemap.
Here is the start of the file we publish, trimmed:
How it relates to robots.txt
Section updated
The two files should agree. Every URL in llms.txt must be allowed for the agents you want to read it; a page listed in llms.txt and blocked in robots.txt is a contradiction the crawler resolves by not fetching. The reverse holds too: pages you block for training crawlers (user content, internal search results, logged-in areas) should not appear in llms.txt. The table summarises what each file does, and the guide to blocking AI crawlers has robots.txt rules that block training and allow answers.
| File | Audience | Says | Enforced by |
|---|---|---|---|
| sitemap.xml | Search engines | Here is everything, with change dates | Nothing; a hint for crawling |
| robots.txt | All crawlers | These agents may or may not fetch these paths | The crawler’s own compliance; server rules for the rest |
| llms.txt | Language models and agents | These pages are worth reading, with summaries | Nothing; a curated suggestion |
Check whether anyone reads it
Section updated
The honest answer to “does llms.txt work?” is “check your server logs”. Most assistants fetch without running JavaScript, so a page script cannot see them; you need server-side records or an access-log import.
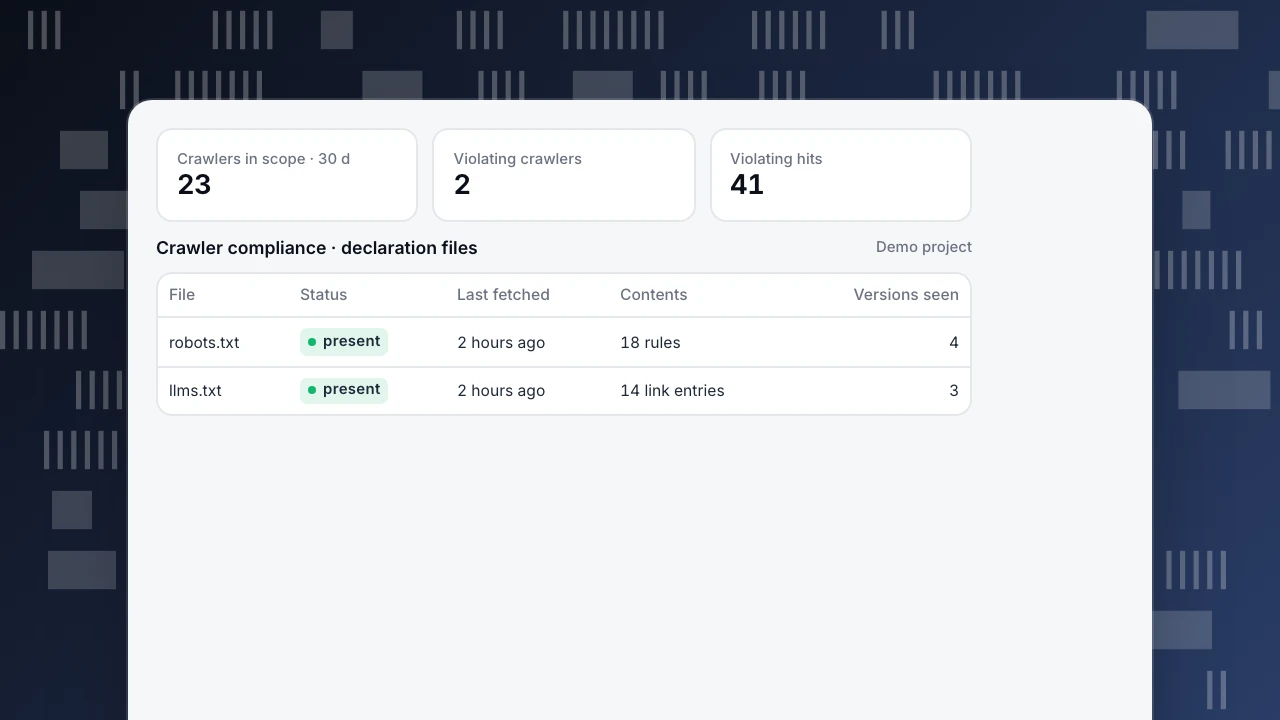
- Confirm the file is reachable. TapCub’s crawler compliance page fetches your robots.txt and llms.txt, shows whether each is present, how many rules or link entries it has and how many versions it has seen, and can draft an llms.txt for you to edit and publish.
- Count fetches of the file. Filter your access log for
GET /llms.txtand group by user agent. A few fetches a month from answer agents is a typical start; none at all after a month means nobody is using it yet. - Compare what agents fetch with what you listed. With server logs connected, crawl health shows each crawler’s most-fetched pages. Check how many of them are in your file. If the share rises after you publish, the file is doing something; if it stays flat, spend your time elsewhere.
TapCub does not compute that listed-page share for you; it is a ten-minute comparison in a spreadsheet, and worth repeating a month after each change to the file. The sample below shows the compliance view of both files in the demo project.
Crawlers in scope · 30 d
23
Violating crawlers
2
Violating hits
41
Crawler compliance · declaration files
Demo project| File | Status | Last fetched | Contents | Versions seen |
|---|---|---|---|---|
| robots.txt | present | 2 hours ago | 18 rules | 4 |
| llms.txt | present | 2 hours ago | 14 link entries | 3 |
Keep it current
Section updated
llms.txt rots like any index. Review it quarterly, and whenever you launch a product page, retire a doc or change pricing. Keep descriptions honest: if an assistant quotes a line about a feature you removed, that came from your file. Add new articles sparingly so the file stays readable on one screen, and note at the top when it was last reviewed.
If your site has several languages, keep each description in the language of the page it points to, and either list each language’s key pages in its own section or publish a file per language directory. Check the compliance page after every edit to make sure the live file is the one you meant to publish.
Common mistakes
Section updated
Five we see repeatedly:
- Listing every page, which makes it a second sitemap.
- Relative URLs, or URLs that redirect or carry tracking parameters.
- Descriptions written as slogans rather than summaries.
- Listing pages that robots.txt blocks for the very agents you want to read them.
- Publishing the file and concluding it does not work without ever checking a log.
Write it in an hour, verify it in a month, and adjust. While you read the log, the AI crawler checker tells you which operator a user agent string belongs to and what it is used for.
FAQ
New section
What is llms.txt?
A Markdown file at the root of a site, proposed in 2024, that gives language models a one-paragraph summary and a curated list of key pages with descriptions. It is voluntary and grants or blocks nothing.
Does Google use llms.txt?
Google says you do not need AI text files or special markup to appear in its AI features; normal SEO practices apply. Write llms.txt for the assistants and agents that do read it, and verify in your logs.
What is the difference between llms.txt and robots.txt?
robots.txt sets which crawlers may fetch which paths. llms.txt suggests which pages are worth reading. Keep them consistent: never list a page in llms.txt that robots.txt blocks for the agents you want to reach.
How do I know if AI crawlers read my llms.txt?
Look for GET requests to /llms.txt in your server access log, grouped by user agent, and compare the pages each crawler fetches with the pages your file lists. A page script cannot see most AI fetchers.
Do I need llms-full.txt as well?
It is optional. llms-full.txt puts full page content in one file, which some documentation sites publish. Start with a short llms.txt; add the full version only if you have docs that agents read often.
See also: AI visibility.
See also: CCBot: Common Crawl's Dataset Crawler and What Blocking It Changes.
See also: AI Visibility Audit: A Five-Step Checklist You Can Repeat.
Update history1
- Major updateRewritten with the format from the proposal, Google's position, a real example and server-log verification. Removed an unsupported metric.
- First published
Was this article helpful?
We use your answers to fix and expand this page.
Couldn’t send. Please try again in a minute.
Thanks for the feedback. We’ll use it to improve this page.You’ve already sent feedback on this page. Thanks.

Technical Engineer
Focuses on tracking code, SDKs, and API integrations, with practical guidance on implementation checks and troubleshooting.