Try it on your own data
Every report in this article is in the free plan. One snippet for web and apps, up to 10 sites.
Start freeDeciding which AI crawlers to let in is now a routine website decision, and most guides stop at a copy-paste robots.txt. This one starts from what each agent actually does, according to its operator, then gives you four policies, the rules for each, what robots.txt cannot enforce, and how to check from your own data that the rules hold and what each assistant sends back.
What you will learn
- Training crawlers, AI search crawlers and user-triggered fetchers need different rules
- Blocking training crawlers does not affect Google Search; blocking AI search removes you from those answers
- Verify with server-side data: most crawlers never run your analytics script
What changed · Nov 3, 2026
Rewritten as a guide to blocking AI crawlers: verified user-agent list, robots.txt rules by purpose, and how to check compliance.
How to block AI crawlers without blocking searchAI crawler user agents and what they doPick a policy before you write rulesWrite the robots.txt rulesEnforce what robots.txt cannotCheck that the rules workReading the AI content ledgerThe number that settles the argumentCommon mistakesFAQ
How to block AI crawlers without blocking search
New section
To block AI crawlers properly, you first need to know which one you are blocking, because "AI crawler" covers three different jobs. Training crawlers collect pages that may be used to train models. AI search crawlers index pages so an assistant can show and link them in its search results. User-triggered fetchers load a page at the moment someone asks an assistant about it. Most vendors run a separate user agent for each job, and a rule that treats "OpenAI" or "Anthropic" as one thing will block more, or less, than you meant.
Search engines are a fourth group and are not affected by any of the rules below unless you name them. If you only want the definition, see what an AI crawler is; this guide is about deciding what to allow and checking that the rules hold.
AI crawler user agents and what they do
New section
The table lists the main agents as their operators document them (checked 2026-11-03). The robots.txt column is the vendor's own statement, not a test result.
| Operator | User agent | Job | robots.txt, per the vendor |
|---|---|---|---|
| OpenAI | GPTBot | Training | Respected; opt out with Disallow |
| OpenAI | OAI-SearchBot | Search results in ChatGPT | Respected |
| OpenAI | ChatGPT-User | Fetches for a user's request | "robots.txt rules may not apply" |
| Anthropic | ClaudeBot | Training | Respected; Crawl-delay supported |
| Anthropic | Claude-SearchBot | Search result quality | Respected |
| Anthropic | Claude-User | Fetches for a user's query | Respected |
| Google-Extended (token only) | Gemini training and grounding | A robots.txt token; no separate user agent in logs | |
| Perplexity | PerplexityBot | Search results in Perplexity, not training | Respected |
| Perplexity | Perplexity-User | Fetches for a user's request | "generally ignores robots.txt rules" |
Sources: OpenAI crawlers, Anthropic crawler policy, Google common crawlers, Perplexity crawlers.
Two facts in that table change most decisions. Google states that Google-Extended "does not impact a site's inclusion in Google Search nor is it used as a ranking signal", so blocking it does not cost you search traffic. And user-triggered fetchers sit outside robots.txt for some vendors, because a person, not a crawler, asked for the page.
Pick a policy before you write rules
New section
Write the policy in one sentence first; the rules follow from it. These are the four we see most often:
| Policy | Allow | Block | Trade-off |
|---|---|---|---|
| Open | Everything | Nothing | Content can be used for training; maximum chance of being cited |
| Block training, allow answers | Search engines, AI search and user fetchers | GPTBot, ClaudeBot, Google-Extended and other training crawlers | Keeps citations and referral visits; your pages stay out of future training sets |
| Block all AI | Search engines only | Every AI agent, including AI search | Assistants cannot cite or link you; regular search is unaffected |
| Private sections only | Public pages | Account, search-result and user-content paths for everyone | Protects what should never be crawled, whatever the bot |
"Block training, allow answers" is the common choice for publishers and SaaS sites that want to appear in assistants' answers. Blocking OAI-SearchBot or Claude-SearchBot removes you from those vendors' search results, so do it only if that is the goal.
Write the robots.txt rules
New section
A robots.txt group is one or more User-agent lines followed by rules; the rules apply to every agent named in the group. Under the standard, RFC 9309, a crawler uses the most specific matching rule, and when an Allow and a Disallow match equally, Allow wins. The same RFC says crawlers should not use a cached copy for more than 24 hours, so expect changes to take up to a day.
A policy that blocks training and allows answers and search looks like this:
# AI training crawlers: not allowed
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
Disallow: /

# AI search and user fetchers: allowed
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
Allow: /

# Everyone: keep private paths out
User-agent: *
Disallow: /account/
Disallow: /search

Sitemap: https://example.com/sitemap.xml
Enforce what robots.txt cannot
New section
The RFC is explicit that these rules "are not a form of access authorization". Well-behaved crawlers follow them; nothing forces the rest. Three cases need a server or CDN rule instead:
- User-triggered fetchers that the vendor says may not follow robots.txt, if you do not want them at all.
- Agents that fetch disallowed paths anyway. Your logs will show it; the file is clearly not working for them.
- Spoofed user agents. Any scraper can call itself GPTBot. Check the source address against the IP lists vendors publish: OpenAI (gptbot.json, searchbot.json, chatgpt-user.json), Anthropic and Perplexity (perplexitybot.json).
Block by verified user agent and IP range at the edge, return a 403, and keep the robots.txt rule as the public statement of intent.
Check that the rules work
New section
Rules you never verify are a guess. You need two things: a record of who fetched what, and your rules next to it.
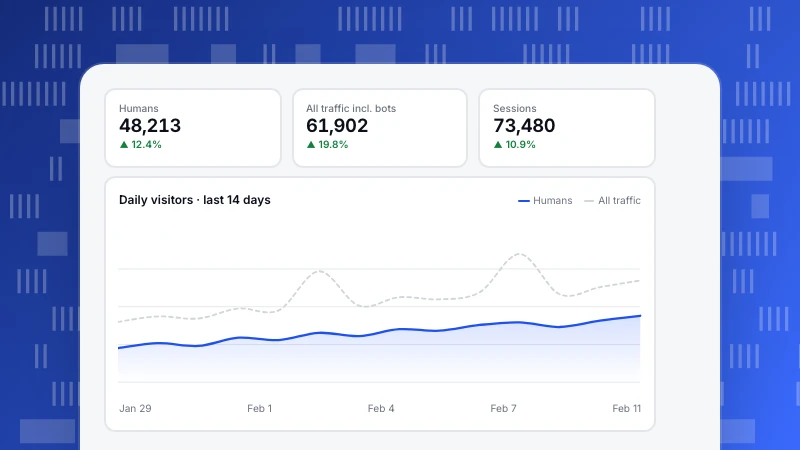
In TapCub the record comes from the Bots report, which separates search, AI training, AI answer and monitoring bots from people. One limit matters here: with only the page script, you see only bots that execute JavaScript, and most crawlers do not. For a complete picture, connect server-side events or import your web server logs (bots and AI crawlers).
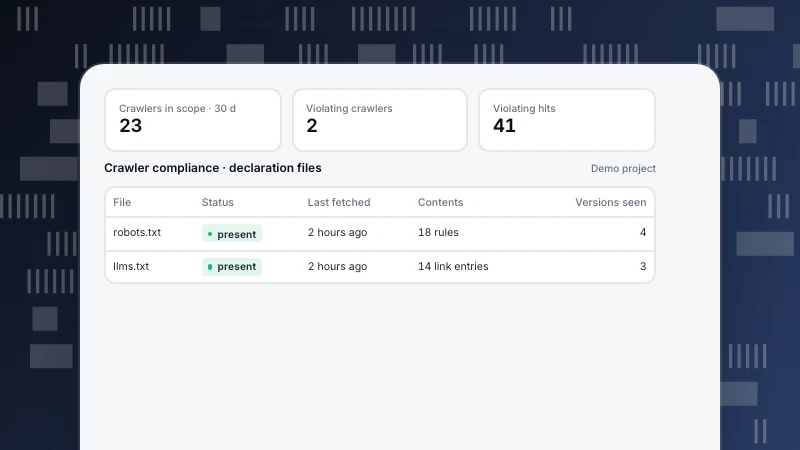
The Crawler compliance page then fetches your robots.txt and compares it with real fetches. It records three kinds of violation: fetched while blocked globally, fetched a disallowed path, and fetched sooner than the declared Crawl-delay. Each crawler gets a trust level (verified, suspected fake, unverified), and a violating row gives you the user-agent token and an Nginx block snippet to copy. A generator drafts rule files for "block training crawlers", "block answer engines" or "search engines only" (crawl health and compliance). Note that adding a crawler to TapCub's exclusion list only stops it being counted; refusing it still happens on your server.
Reading the AI content ledger
New section
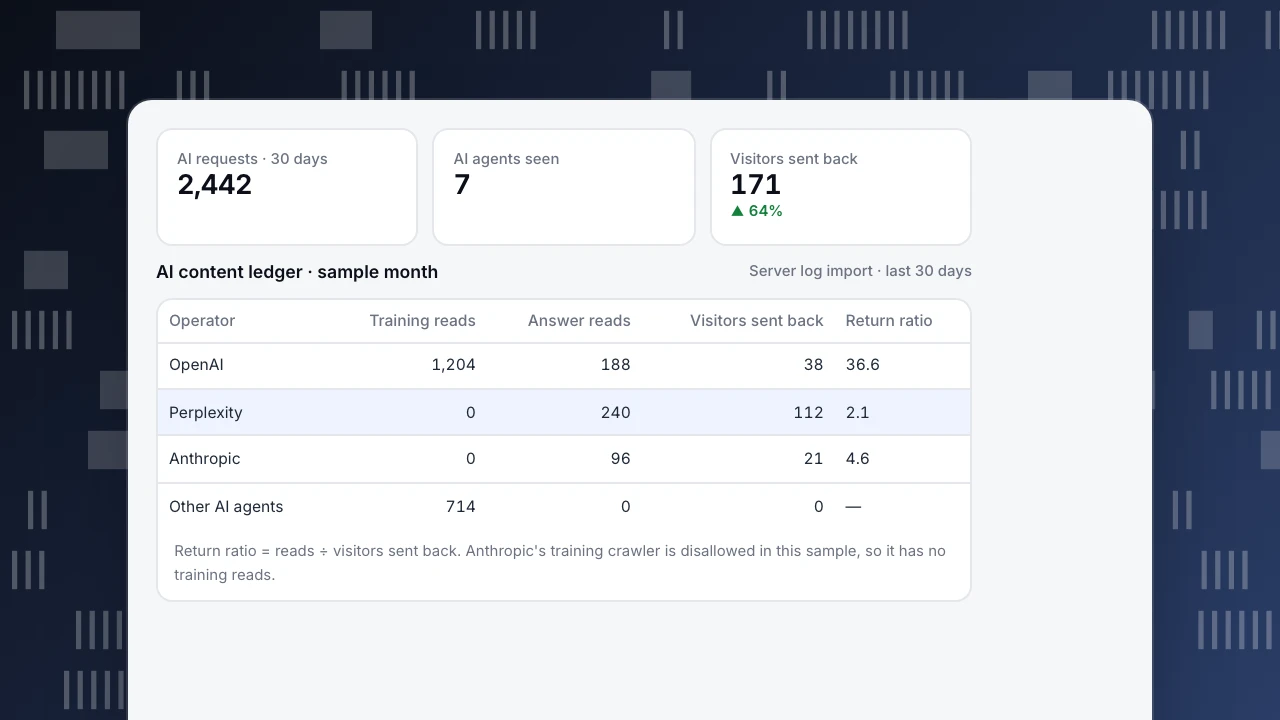
Blocking is half of the decision; the other half is what each assistant gives back. The AI content ledger on the Bots report lists, per operator, reads by training crawlers and by answer engines in separate columns, human visitors that operator sent back, and a return ratio: reads divided by visitors sent back. A large ratio means many reads and few people.
AI requests · 30 days
2,442
AI agents seen
7
Visitors sent back
171
▲ 64%
AI content ledger · sample month
Server log import · last 30 days| Operator | Training reads | Answer reads | Visitors sent back | Return ratio |
|---|---|---|---|---|
| OpenAI | 1,204 | 188 | 38 | 36.6 |
| Perplexity | 0 | 240 | 112 | 2.1 |
| Anthropic | 0 | 96 | 21 | 4.6 |
| Other AI agents | 714 | 0 | 0 | — |
Return ratio = reads ÷ visitors sent back. Anthropic's training crawler is disallowed in this sample, so it has no training reads.
The number that settles the argument
New section
Visitors sent back is the column that turns opinion into a number. In the sample, Perplexity read a fraction of what OpenAI read and sent three times the visitors, because its reads are answer fetches rather than training. Anthropic's training crawler was disallowed and made no reads. Use that pattern to decide: an agent with many reads and no visitors is a candidate for blocking; an agent that sends people is worth allowing, and worth pointing at your strongest pages with an llms.txt file.
AI-referred visits also appear as their own channel on the Sources report, counted as human sessions, so you can see which pages assistants cite and whether those visitors convert. Review the ledger monthly; vendors add and rename agents every few months.
Common mistakes
New section
- Treating one vendor as one bot. Disallowing every OpenAI agent also removes you from ChatGPT search results.
- Blocking Googlebot to stay out of AI. That removes you from Google Search. Google-Extended is the token for Gemini training and grounding.
- Expecting instant effect. Crawlers may cache robots.txt for up to 24 hours.
- Putting rules on the wrong host. robots.txt applies per host and protocol; www, the apex domain and each subdomain need their own file.
- Judging from JavaScript data alone. Most crawlers never run your script, so a script-only report undercounts them.
FAQ
New section
Does blocking GPTBot or ClaudeBot hurt Google rankings?
No. They are training crawlers from OpenAI and Anthropic and have nothing to do with Google Search. Even Google's own Google-Extended token does not affect inclusion or ranking in Google Search, according to Google.
Will blocking GPTBot stop ChatGPT from citing my site?
Not by itself. GPTBot is for training. Search results in ChatGPT come from OAI-SearchBot, and fetches on a user's request come from ChatGPT-User, which OpenAI says may not follow robots.txt.
Do AI crawlers respect robots.txt?
The major vendors say their training and search crawlers do. Some user-triggered fetchers may not, by the vendors' own documentation. Verify with your logs and block at the server where needed.
How long does a robots.txt change take to apply?
Up to about a day. RFC 9309 says crawlers should not rely on a cached copy for more than 24 hours.
Is robots.txt legally binding?
The standard itself says its rules are not access authorization. Treat robots.txt as a public statement of your policy and use server rules for enforcement.
See also
- Meta-ExternalAgent: What Meta’s AI Crawler Does and How to Control It
- Bytespider: What It Is and How to Control It
- AI visibility
See also: PerplexityBot: What It Reads, What It Sends Back, and Whether to Allow It.
See also: Agent Analytics: How to Tell AI Agents From Human Visitors.
Update history1
- Major updateRewritten as a guide to blocking AI crawlers: verified user-agent list, robots.txt rules by purpose, and how to check compliance.
- First published
Was this article helpful?
We use your answers to fix and expand this page.
Couldn’t send. Please try again in a minute.
Thanks for the feedback. We’ll use it to improve this page.You’ve already sent feedback on this page. Thanks.

Technical Engineer
Focuses on tracking code, SDKs, and API integrations, with practical guidance on implementation checks and troubleshooting.