Try it on your own data
Every report in this article is in the free plan. One snippet for web and apps, up to 10 sites.
Start freePublic website traffic data comes in three kinds: exact counts that owners publish (Wikimedia's page views), rankings from sampled signals (Tranco, Cloudflare Radar) and browser telemetry (CrUX). Only the first measures traffic; the others are popularity proxies. No public source gives visits for an arbitrary private site, so record the unit, window and date of every number.
What you will learn
- Only owner-published counts such as Wikimedia's measure traffic; ranks and telemetry are popularity proxies in different units
- 35.6% of English Wikipedia's 2025 requests were not user traffic, and a top-40 domain's rank moved 29% in 39 days
- Record source, unit, scope, window and date pulled next to every public number so it can be re-checked
What public website traffic data actually exists?
Public traffic data comes in three kinds, and they are not interchangeable: exact counts that an owner chooses to publish, rankings built from sampled signals, and browser telemetry that describes experience rather than volume. No public source gives you visits for an arbitrary private website. Knowing which kind you hold decides how far you can trust it.
The sources below are all free to read, and we queried or read each one directly on 2026-11-19 and 2026-11-20. Four things to check for any traffic data you find: who measured it, what was counted (visits, pageviews, DNS lookups or users), over which window, and whether bots were removed.
Which source gives what, from which sample, and how reliable is it?
| Source | What it reports | Sampling and window | Reliability for traffic |
|---|---|---|---|
| Wikimedia Pageviews API | Page views per page or per project for Wikimedia sites, split by user and automated agents, since May 2015 | Full counts; automated traffic filtered with its own bot detection | Exact for that site only |
| Tranco | A rank for each of one million domains, updated daily | Averages the rankings of several providers over the previous 30 days | A rank only; moves daily |
| Cloudflare Radar domain rankings | An ordered top 100, then unordered rank buckets from 200 to 1,000,000 | Built from anonymized 1.1.1.1 resolver lookups; popularity is the estimated size of the user population that looks a domain up | Order of magnitude only |
| Chrome User Experience Report (CrUX) | Real-user performance distributions and a coarse popularity bucket for origins, monthly in BigQuery since 2017 | Eligible Chrome users, on origins that are publicly discoverable and sufficiently popular | Presence is a floor; no visit counts |
| Provider free data (blended estimates) | Visit estimates and rankings, with the provider stating it blends several sources | A model; per-site sample not published | An estimate; calibrate it |
A table like this makes one thing clear: only the first row is a measurement of traffic. The other rows are proxies for popularity.
| Source | What it reports | Reliability for traffic |
|---|---|---|
| Wikimedia Pageviews API | Page views by user vs automated agents, since May 2015 | Exact for that site only |
| Tranco | One rank per domain for a million domains, 30-day average of several providers | A rank only; moves daily |
| Cloudflare Radar rankings | Ordered top 100, then unordered buckets from 200 to 1,000,000 | Order of magnitude only |
| Chrome User Experience Report | Real-user performance and a coarse popularity bucket, monthly | Presence is a floor; no visit counts |
| Provider free data | Blended visit estimates and ranks | An estimate; calibrate it |
Source descriptions checked against each provider's documentation on 2026-11-20.
How do you pull the data yourself?
You do not need an account for the first two sources. Run these from a terminal; they are the same calls used for the examples in this article.
- Wikimedia monthly page views for English Wikipedia, 2025, user traffic only:
curl "https://wikimedia.org/api/rest_v1/metrics/pageviews/aggregate/en.wikipedia.org/all-access/user/monthly/2025010100/2025120100"
Change user to all-agents to include automated traffic.
- A domain's Tranco rank history:
curl "https://tranco-list.eu/api/ranks/domain/example.com"returns one rank per daily list. - CrUX in BigQuery: the dataset is free up to BigQuery's monthly free tier. The
metrics_summarytable gives a coarse popularity bucket per origin and month. - Cloudflare Radar: open the Domains page and download the bucket CSV. Remember the order inside a bucket is intentionally hidden.
Write down the date you pulled each number. Rankings and monthly figures change, and a number without a date cannot be checked later.
Worked example: what exact public data still tells you about noise
Even the one exact source shows how unstable "traffic" is as a concept. Real data pulled on 2026-11-20 from Wikimedia's API for English Wikipedia, 2025:
- Volume. User page views by month ran from 8,075,023,328 in January to 6,637,486,973 in June, a ratio of 8.075 ÷ 6.637 = 1.22. The 2025 total was 85,541,514,536, which is about 7.13 billion a month.
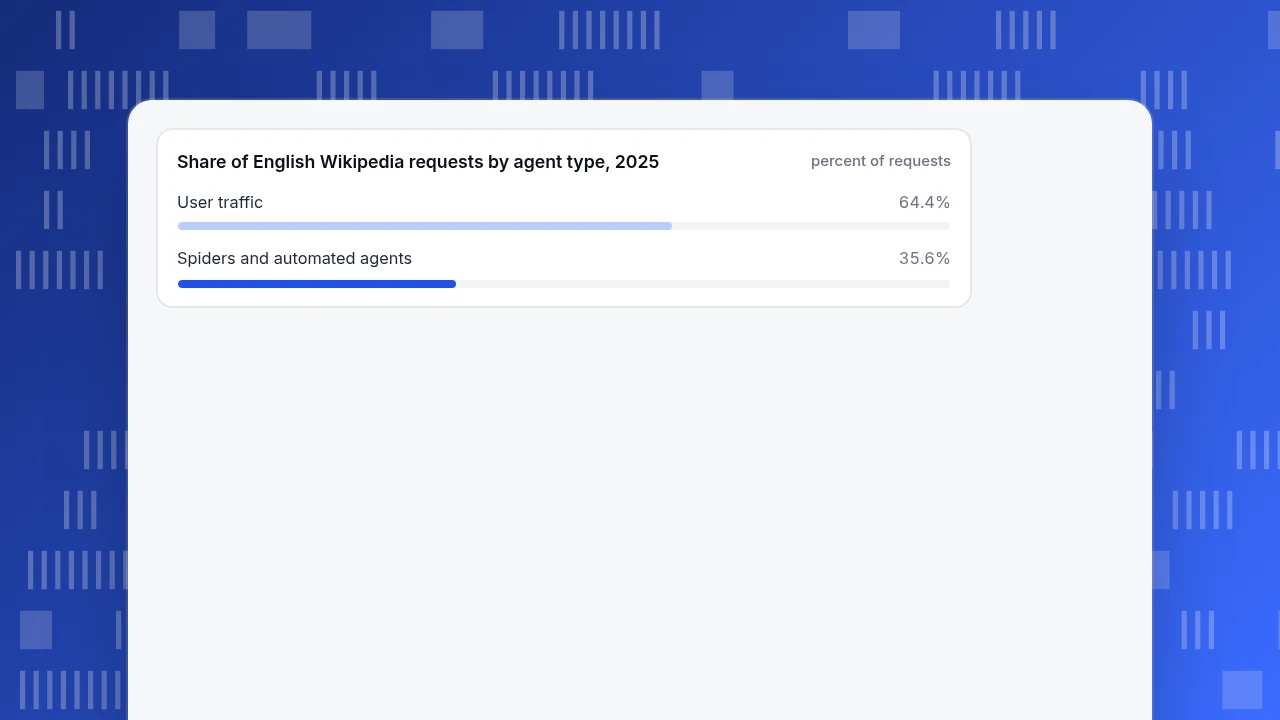
- Bot share. Including all agents the year total was 132,913,760,903. User traffic was 85.54 ÷ 132.91 = 64.4%, so 35.6% of counted requests were automated.
- The share moves. By month, the user share ranged from 57.8% in September to 70.6% in October, a swing of 12.8 points between two consecutive months.
Then ranks, from Tranco for 39 daily lists, 2026-10-12 to 2026-11-19: wikipedia.org ranged between 31 and 40, a swing of (40 − 31) ÷ 31 = 29.0%; example.com between 165 and 186, 12.7%.
What this means for anyone reading public data:
- A 20% month-to-month difference in an exact count can be seasonal, not a trend.
- The "human share" is itself a measurement that moves, so two sources that classify bots differently can disagree without either being wrong.
- A rank change of a few places at the top is not a signal; compare ranks over weeks, not days.
Share of English Wikipedia requests by agent type, 2025
percent of requestsWhat can no public source tell you?
Four gaps remain whichever source you pick, and each one is a reason to avoid quoting a single number as fact.
| Unit counted | Source | Can you convert it to visits? |
|---|---|---|
| Page views | Wikimedia | Not without knowing pages per visit, which the API does not give |
| Domain lookups by a population of resolver users | Cloudflare Radar | No: lookups are not visits, and the resolver's users are not all internet users |
| Eligible Chrome user experiences | CrUX | No: only some Chrome users are included, and Chrome does not publish what share |
| Rank position | Tranco | No: a rank has no unit |
- No unit matches. The table shows four different units. A visit, a page view, a lookup and a rank are different things, so you cannot subtract one source from another.
- No sample is the whole web. Each source sees only its own slice: one site's own servers, one resolver's users, one browser's opted-in users.
- No source is fresh. Radar's buckets used a seven-day window when launched, Tranco uses 30 days and CrUX publishes monthly, so a campaign that started last week is invisible in several of them.
- No source removes bots the same way. Wikimedia's figures show how large the difference can be, and every other source applies its own rule.
How should you record a public number so it can be checked later?
A public number is only useful if someone else can find it again. Write five things next to every figure you keep:
- Source and endpoint, for example "Wikimedia Pageviews API, aggregate".
- Unit, for example "page views, user agents only".
- Scope, for example "en.wikipedia, all-access".
- Window, for example "January to December 2025".
- Date pulled, for example "2026-11-20".
Then a number such as "85,541,514,536 user page views, English Wikipedia, 2025, pulled 2026-11-20 from the Wikimedia API" can be re-run and compared. A number written as "Wikipedia gets about 7 billion visits a month" cannot: it changes the unit from page views to visits, and it has no window and no date.
How do you choose a source for a given question?
Use this decision order.
- Is the site run by someone who publishes numbers? Use their numbers. Wikimedia is the standard example; some companies publish statistics in filings or public pages.
- Do you need a relative order across many sites? Use a rank list, and use a 30-day average such as Tranco's rather than a single day. Treat ranks that differ by less than the swing you measure (6% to 29% in the example below) as tied.
- Do you need order of magnitude? A Cloudflare rank bucket or presence in CrUX will tell you whether a site is in the hundred-thousands or the millions, not more.
- Do you need experience, not volume? CrUX gives real-user performance distributions for eligible origins.
- Do you need a visit number for a private site? There is none public. Use a blended estimate, and calibrate it on sites you know, as in how many visitors does a website get; the benchmark roundup in website traffic statistics shows which published figures hold up.
What can you publish about your own traffic with TapCub?
TapCub does not collect traffic for other websites, so it is not a source of public data about competitors. What it can do is make your own numbers exact and, if you want, public. The workflow:
- Install the script and open Web analytics › Overview for your own visitors, sessions and pageviews. Recognised bots and AI crawlers are counted separately in Web analytics › Bots, so your human totals are not inflated by the 35.6% kind of automated traffic Wikimedia's data shows.
- Note the date you read each number, and use the date picker so the window is the same each time you compare.
- To publish, go to Configuration › Settings › Public sharing. It creates a read-only link; you can add a password, choose which modules to open (overview, pages, sources, audience, bots) and limit how many days of history the link can show.
- Know what cannot be shared: the visitor list and sessions are never available through a public link.
- Mark launches and campaigns with Configuration › Annotations, so anyone reading your numbers can see why a month jumped.
FAQ
Is there public data on how much traffic a website gets?
Only when the owner publishes it. Wikimedia is a clear example, with a public API that reports page views. For other sites there are rankings and estimates, not exact visit counts.
How reliable is Tranco or other top-site lists?
They are reliable as popularity ranks, not as traffic. Tranco averages several providers over 30 days to make the list stable, yet we saw wikipedia.org move between rank 31 and 40 in 39 days. The Tranco authors also note that source rankings disagree and can be manipulated.
Does CrUX show how many visitors a site has?
No. CrUX reports real-user performance for origins that are publicly discoverable and sufficiently popular. Being included tells you a site has enough Chrome visitors to measure, but not how many.
Do public traffic figures include bots?
It depends on the source. Wikimedia filters automated traffic and still reports it separately: 35.6% of English Wikipedia's counted requests in 2025 were not user traffic. For other sources, assume bots may be mixed in until the provider says otherwise.
Why do two sources show different traffic for the same site?
They count different things over different windows: lookups, visits, pageviews or users, with different bot rules. Compare the same source over time, and use a second source only for order of magnitude.
Sources
- Wikimedia. Pageviews analytics API: getting started and Pageviews data lake documentation — data since May 2015, bot filtering, user vs all-agents; queried 2026-11-20.
- Tranco. Tranco: a research-oriented top sites ranking — 30-day average of provider rankings, daily update, API; rank histories queried 2026-11-19.
- Cloudflare. Radar Domain Rankings — ordered top 100, unordered buckets from 200 to 1,000,000, resolver-based popularity. Checked 2026-11-20.
- Google Chrome. CrUX methodology and CrUX in BigQuery — eligibility rules, monthly tables since 2017. Checked 2026-11-20.
Was this article helpful?
We use your answers to fix and expand this page.
Couldn’t send. Please try again in a minute.
Thanks for the feedback. We’ll use it to improve this page.You’ve already sent feedback on this page. Thanks.

Data Engineer
Writes about event design, data quality, and collection workflows, with verifiable implementation methods for reliable analytics.